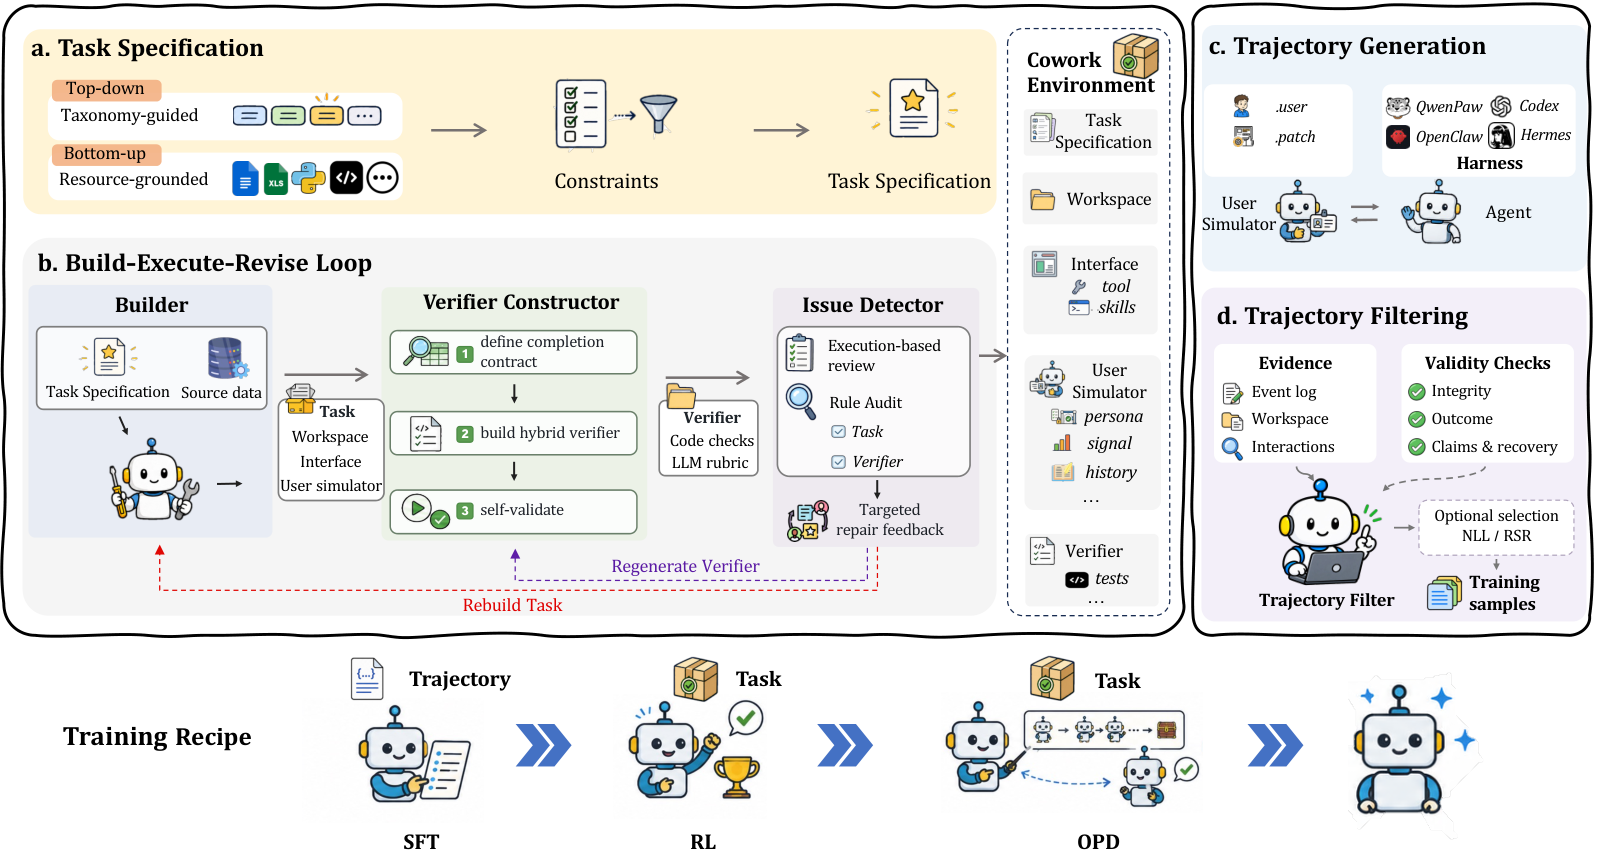
Cowork-Gym: Synthesizing Interactive Work Environments at Scale
Synthesizes 64.9K interactive work environments through a build–execute–revise loop and stateful user simulation for agent post-training.通过构建、执行与修订闭环及有状态用户模拟,合成 6.49 万个交互式工作环境,用于智能体后训练。
I am Xinji Mai (Shinji Mai), an Algorithm Engineer at Tongyi Lab, Alibaba Group, working on agentic reinforcement learning. My research focuses on self-evolving agents, reasoning, and scaling laws for agentic RL.我是麦新纪(Shinji Mai),目前担任阿里巴巴集团通义实验室算法工程师,从事智能体强化学习(Agentic RL)研究,关注自进化智能体、推理能力,以及智能体强化学习的规模化规律。
I received my master’s degree in Computer Technology from Fudan University and my bachelor’s degree in Microelectronics Science and Engineering from Sun Yat-sen University.我硕士毕业于复旦大学计算机技术专业,本科毕业于中山大学微电子科学与工程专业。
Synthesizes 64.9K interactive work environments through a build–execute–revise loop and stateful user simulation for agent post-training.通过构建、执行与修订闭环及有状态用户模拟,合成 6.49 万个交互式工作环境,用于智能体后训练。
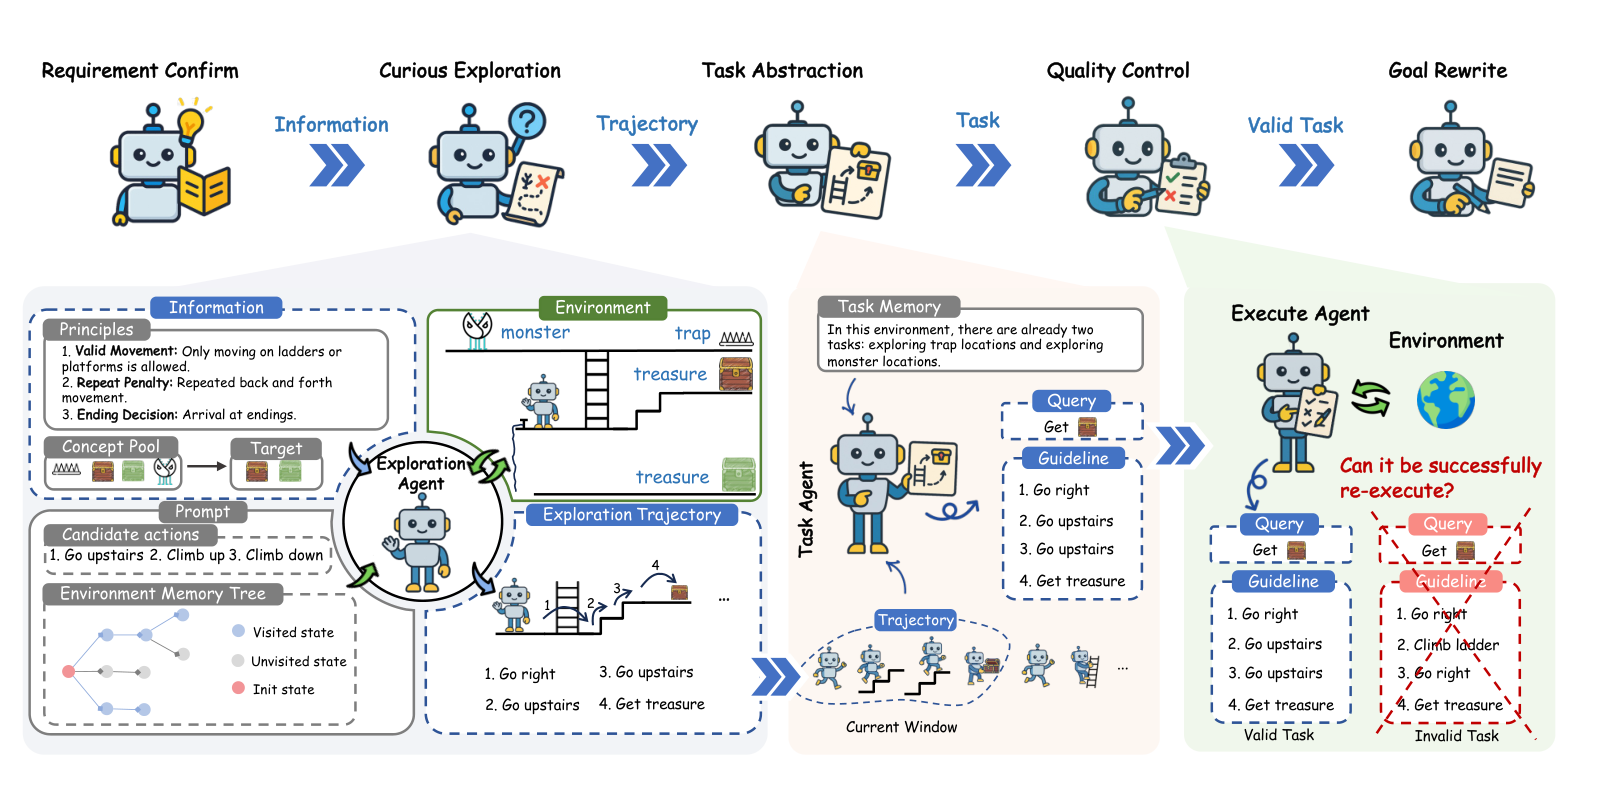
Curiosity-guided exploration grounds synthetic tasks in executable environments for agentic reinforcement learning.以好奇心引导环境探索,在可执行的环境中合成智能体强化学习任务。
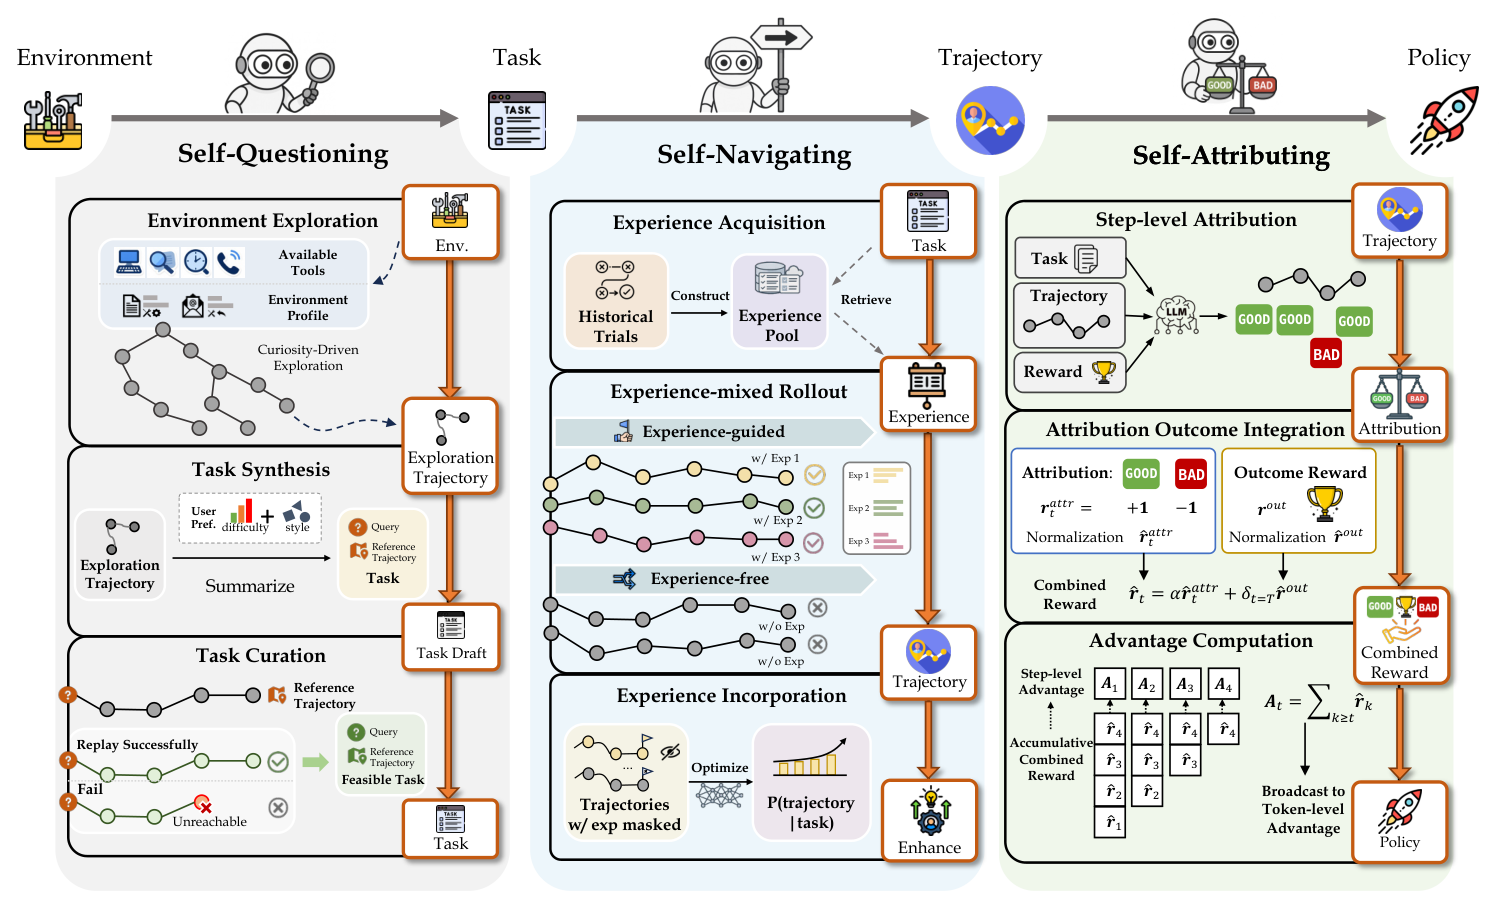
Combines self-questioning, self-navigating, and self-attributing to help agents learn from their own experience.结合自主提问、自主探索与自主归因,让智能体从自身经验中持续学习。
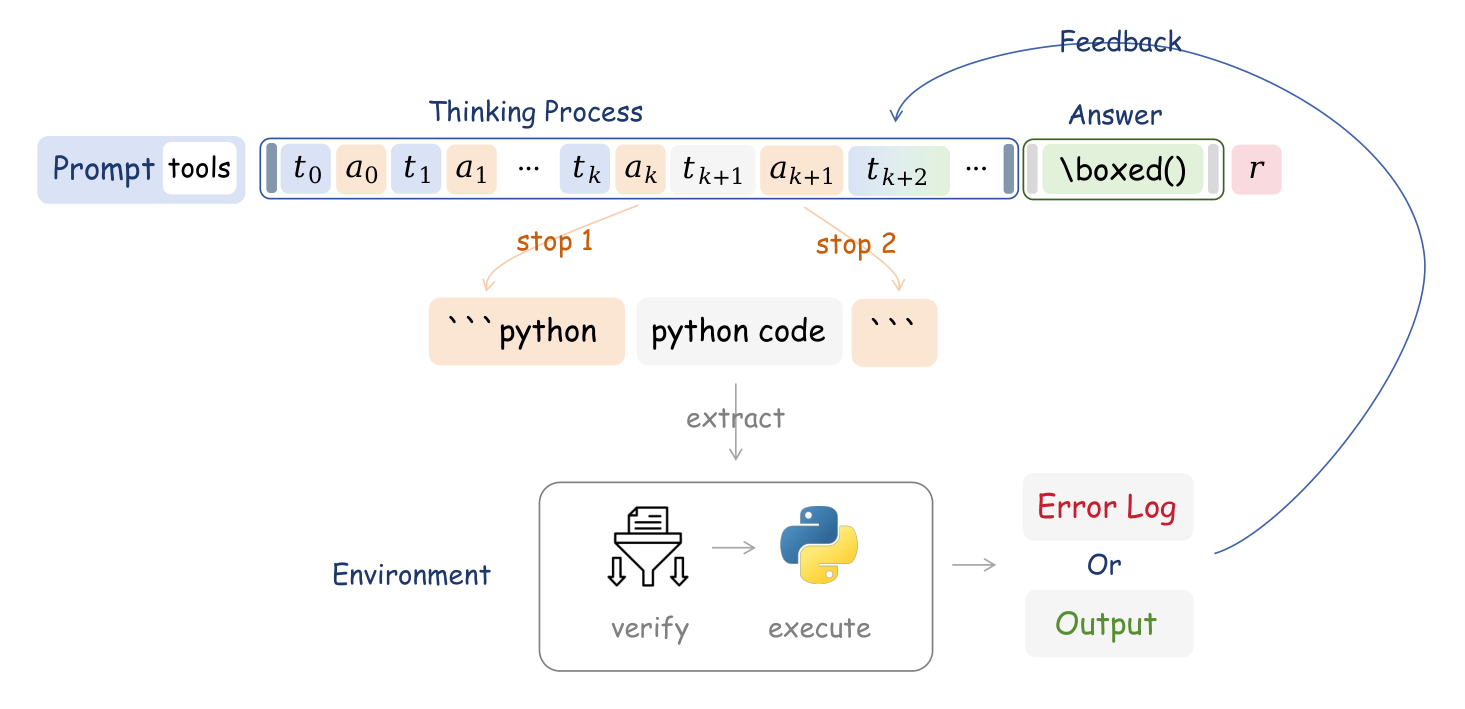
Studies how reinforcement learning teaches models to use code for mathematical reasoning, and how this ability scales.研究强化学习如何让模型自主调用代码进行数学推理,以及这种能力的规模化规律。
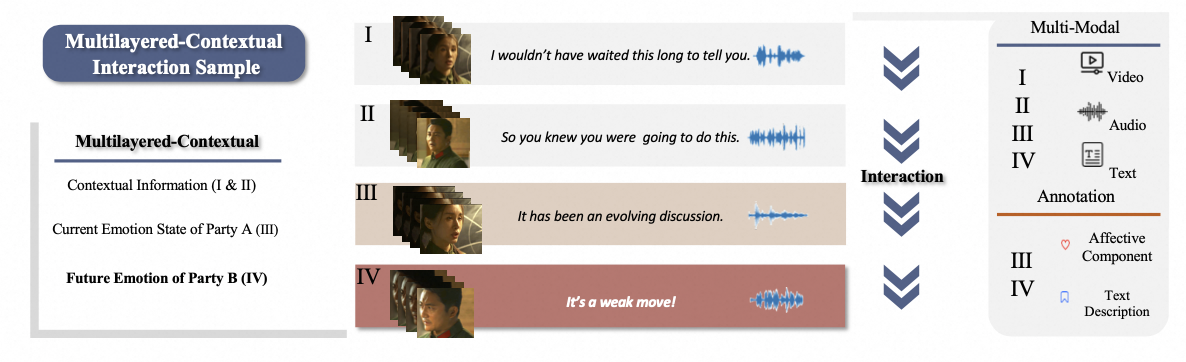
Introduces a benchmark and multimodal framework for forecasting emotions in human interactions.构建人际互动中的情绪预测基准,并提出多模态预测框架。
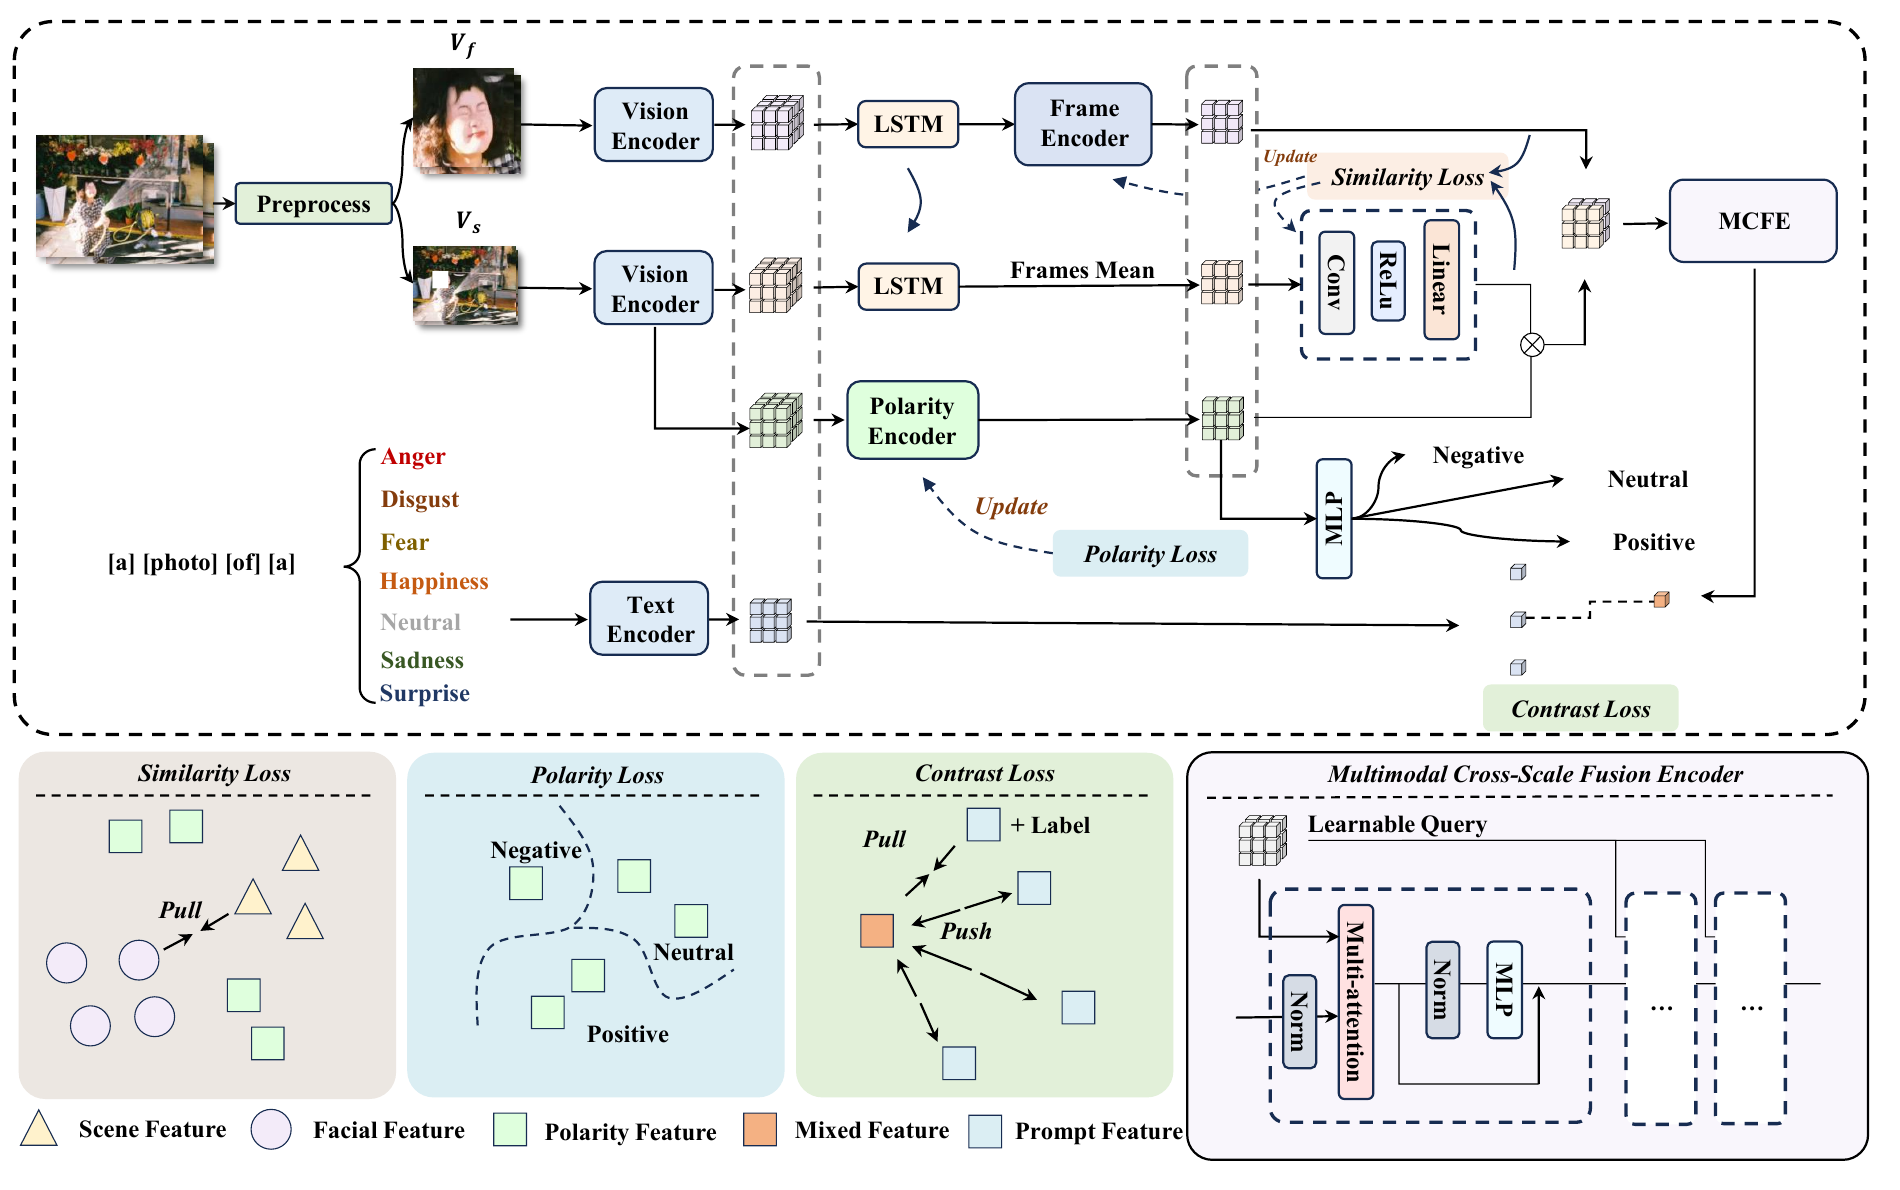
Connects scene context with facial features to support more context-aware emotion recognition.联结场景上下文与面部特征,让情绪识别更充分地理解情境。
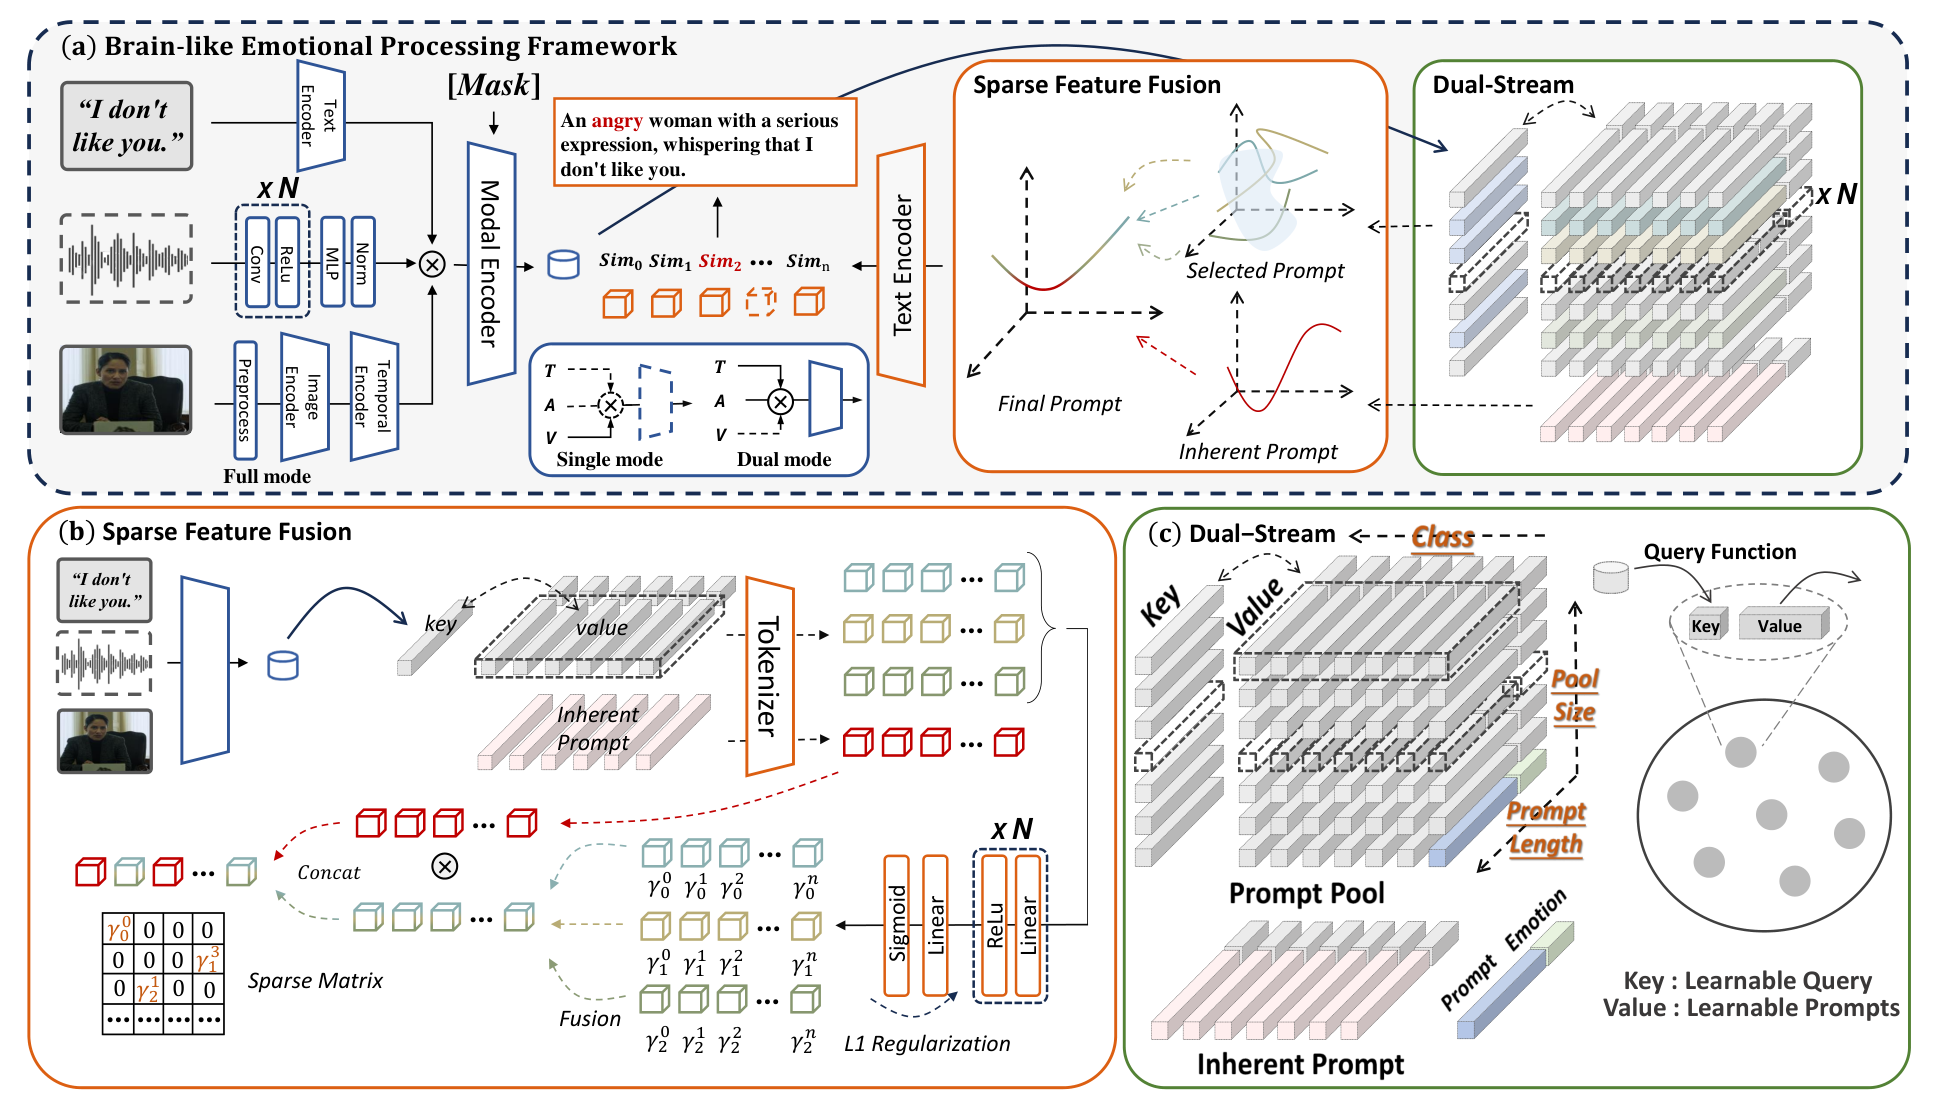
Unifies multimodal emotion signals through a brain-inspired emotional central mechanism.通过脑启发的情感中枢机制,统一建模多模态情绪信号。
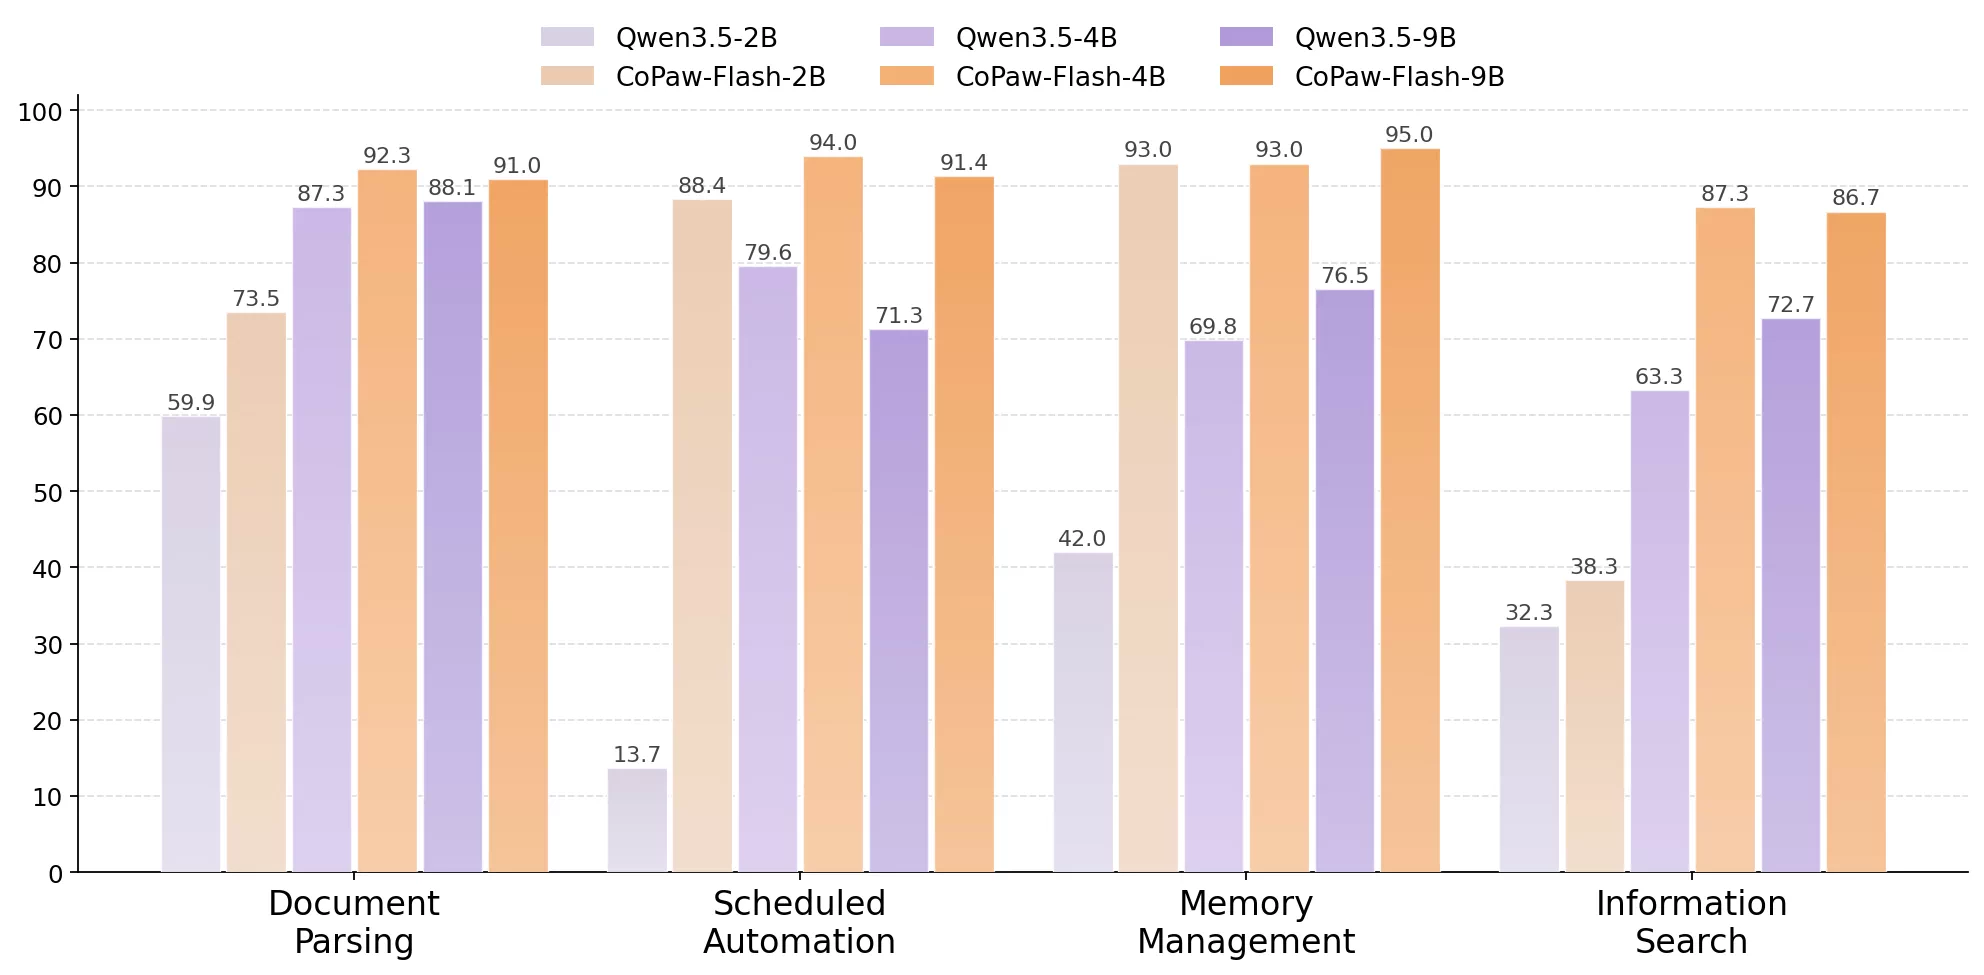
Tool use, command execution, memory, and multi-step planning. Original weights and Q8_0 / Q4_K_M quantizations in five sizes.面向工具调用、命令执行、记忆管理与多步规划,提供五种尺寸的原始权重与 Q8_0 / Q4_K_M 量化版本。
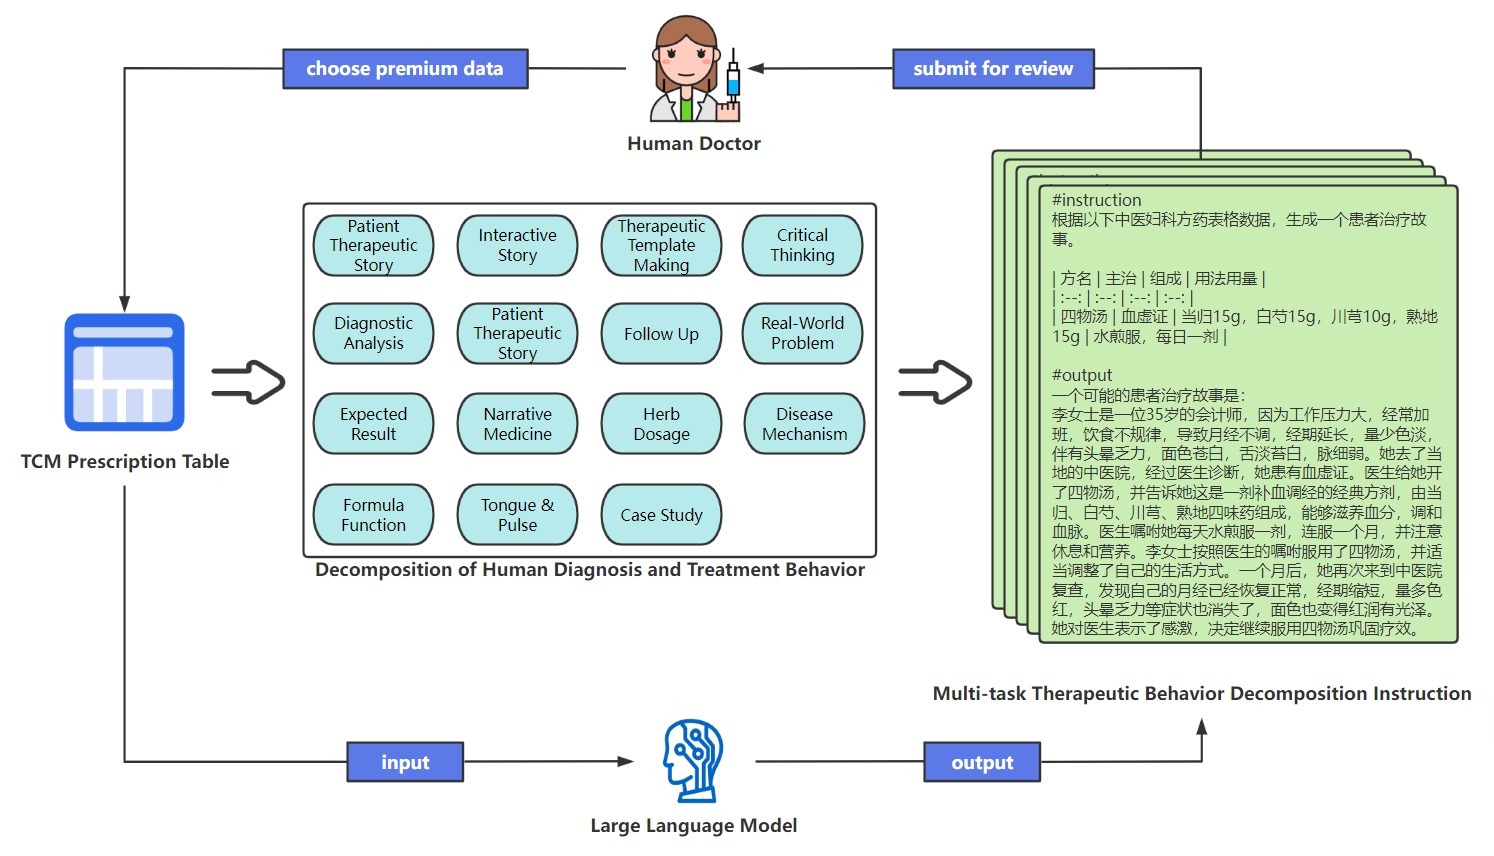
The Zhongjing family of language models for Traditional Chinese Medicine, with 13B and 1.8B releases.面向中医领域的 Zhongjing 系列大语言模型,涵盖 13B 与 1.8B 版本。
SELF-EVOLVING AGENTS自进化智能体
Combines self-questioning, self-navigating, and self-attributing to help agents learn from their own experience.结合自主提问、自主探索与自主归因,让智能体从自身经验中持续学习。
TOOL-INTERACTIVE REINFORCEMENT LEARNING工具交互强化学习
Asynchronous reinforcement learning and tool interaction for spontaneous Python execution and mathematical reasoning.支持异步强化学习与工具交互,让模型自主生成、执行 Python 代码,探索数学推理能力的规模化规律。
2026.07 – Present至今

Algorithm Engineer · Shanghai算法工程师 · 上海
Agentic reinforcement learning, self-evolving agents, and reasoning.智能体强化学习、自进化智能体与推理能力研究。
2025.05 – 2026.07
Reinforcement Learning Algorithm Intern · Shanghai强化学习算法实习生 · 上海
Self-evolving agent training, synthetic interaction data, and reward modeling; contributed to AgentEvolver.自进化智能体训练、交互数据合成与奖励建模,参与 AgentEvolver 开源项目。
2024.12 – 2025.05
Large Language Model Algorithm Intern · Shanghai大模型算法实习生 · 上海
Mathematical reasoning data synthesis and reinforcement learning with code execution, including Agentic RL Scaling Law.数学推理数据合成与代码执行强化学习,参与 Agentic RL Scaling Law 研究。
2024.07 – 2024.12
Multimodal LLM Algorithm Intern · Shanghai多模态大模型算法实习生 · 上海
Multimodal models and object detection for intellectual-property audits and e-commerce platform governance.面向电商平台治理的知识产权审核、多模态模型训练与目标检测。

Master’s · Computer Technology硕士 · 计算机技术
2023.09 – 2026.06
Bachelor’s · Microelectronics Science and Engineering本科 · 微电子科学与工程
2019.09 – 2023.06
A little pixel world, a curious little agent.一个像素世界,一位充满好奇心的探索者。