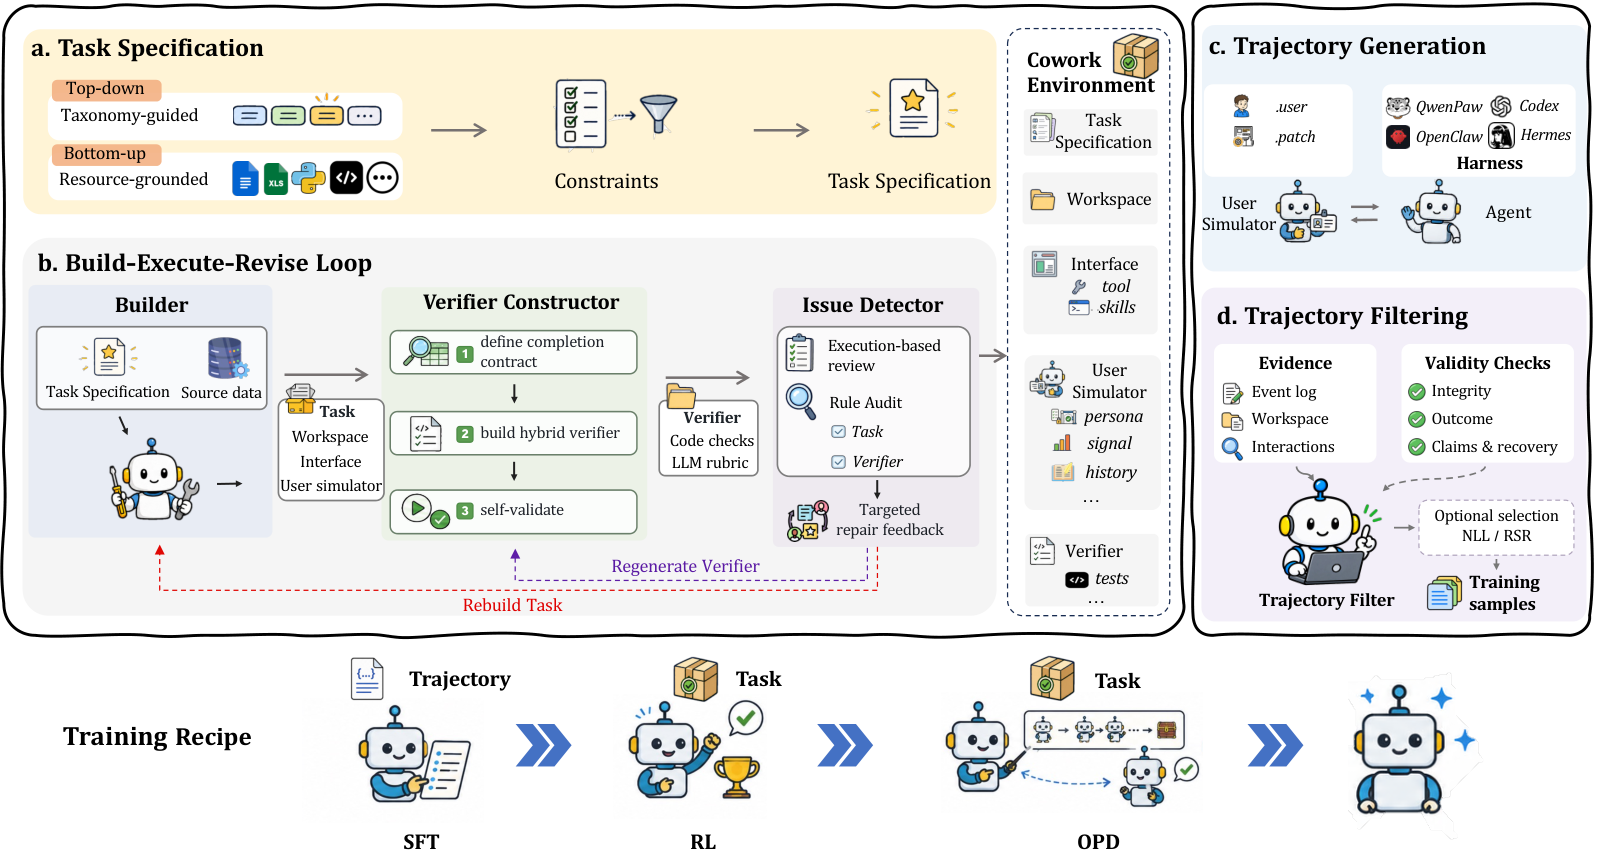
Cowork-Gym: Synthesizing Interactive Work Environments at Scale
Synthesizes 64.9K interactive work environments through a build–execute–revise loop and stateful user simulation for agent post-training.通过构建、执行与修订闭环及有状态用户模拟,合成 6.49 万个交互式工作环境,用于智能体后训练。
XINJI MAI / PUBLICATIONS研究成果
Agentic reinforcement learning, self-evolving agents, and multimodal intelligence.智能体强化学习、自进化智能体与多模态智能。
Synthesizes 64.9K interactive work environments through a build–execute–revise loop and stateful user simulation for agent post-training.通过构建、执行与修订闭环及有状态用户模拟,合成 6.49 万个交互式工作环境,用于智能体后训练。
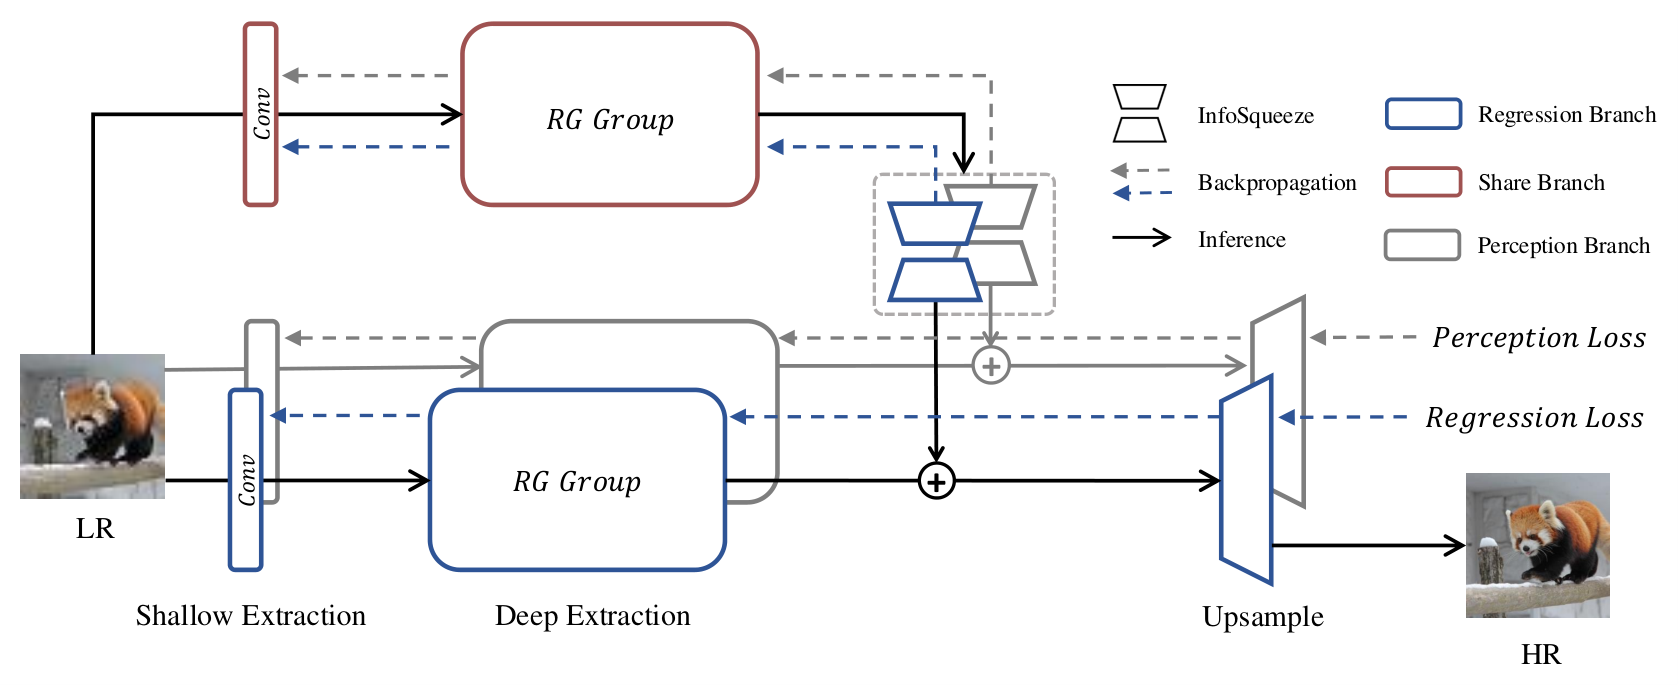
SFR decouples fidelity and perceptual objectives through shared representations, with InfoSqueeze filtering redundant features for blind super-resolution.SFR 通过共享表征解耦保真度与感知质量优化目标,并以 InfoSqueeze 过滤冗余特征,改善盲超分辨率的目标平衡。
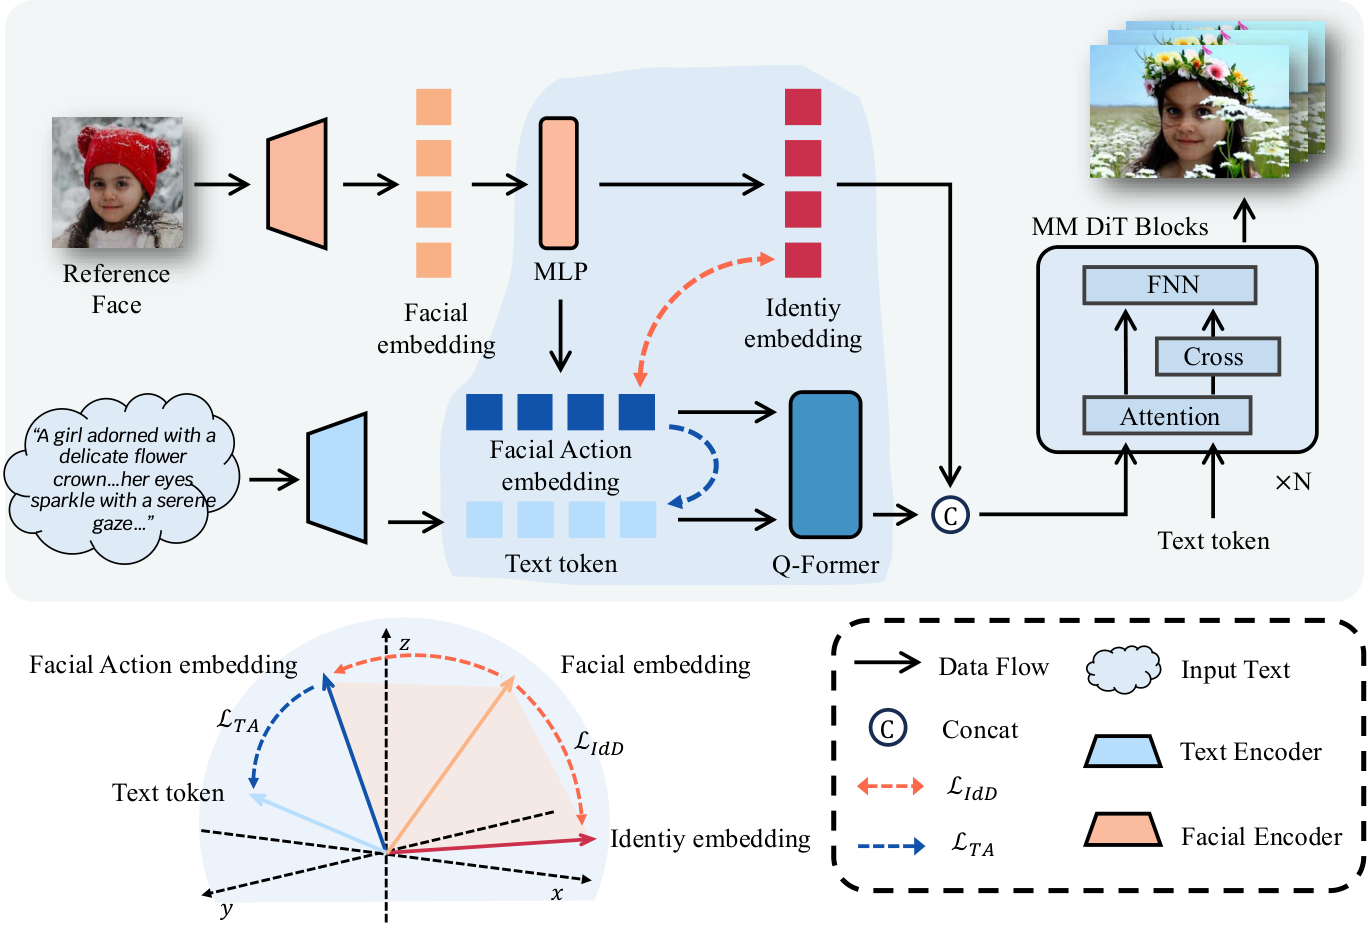
IaD separates identity and facial action features to generate identity-consistent videos with text-controlled expressions, without subject-specific fine-tuning.IaD 分离身份与面部动作特征,在无需针对特定人物微调的情况下,生成身份一致且表情受文本控制的人像视频。
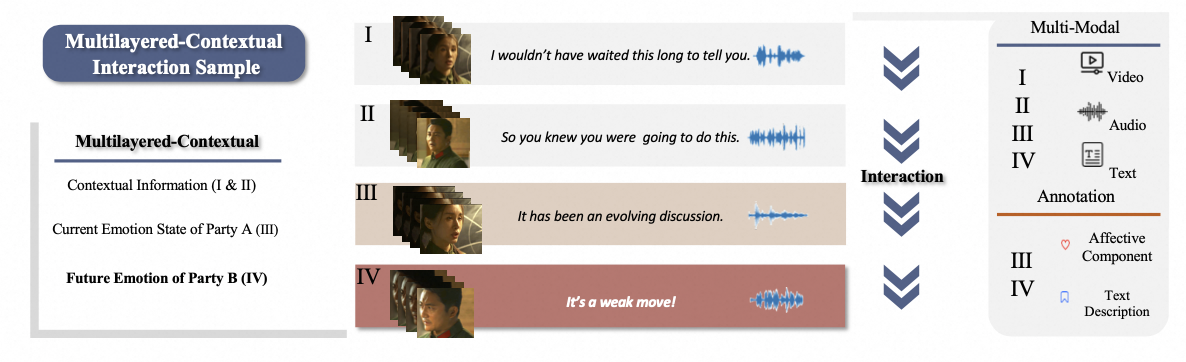
Introduces a benchmark and multimodal framework for forecasting emotions in human interactions.构建人际互动中的情绪预测基准,并提出多模态预测框架。
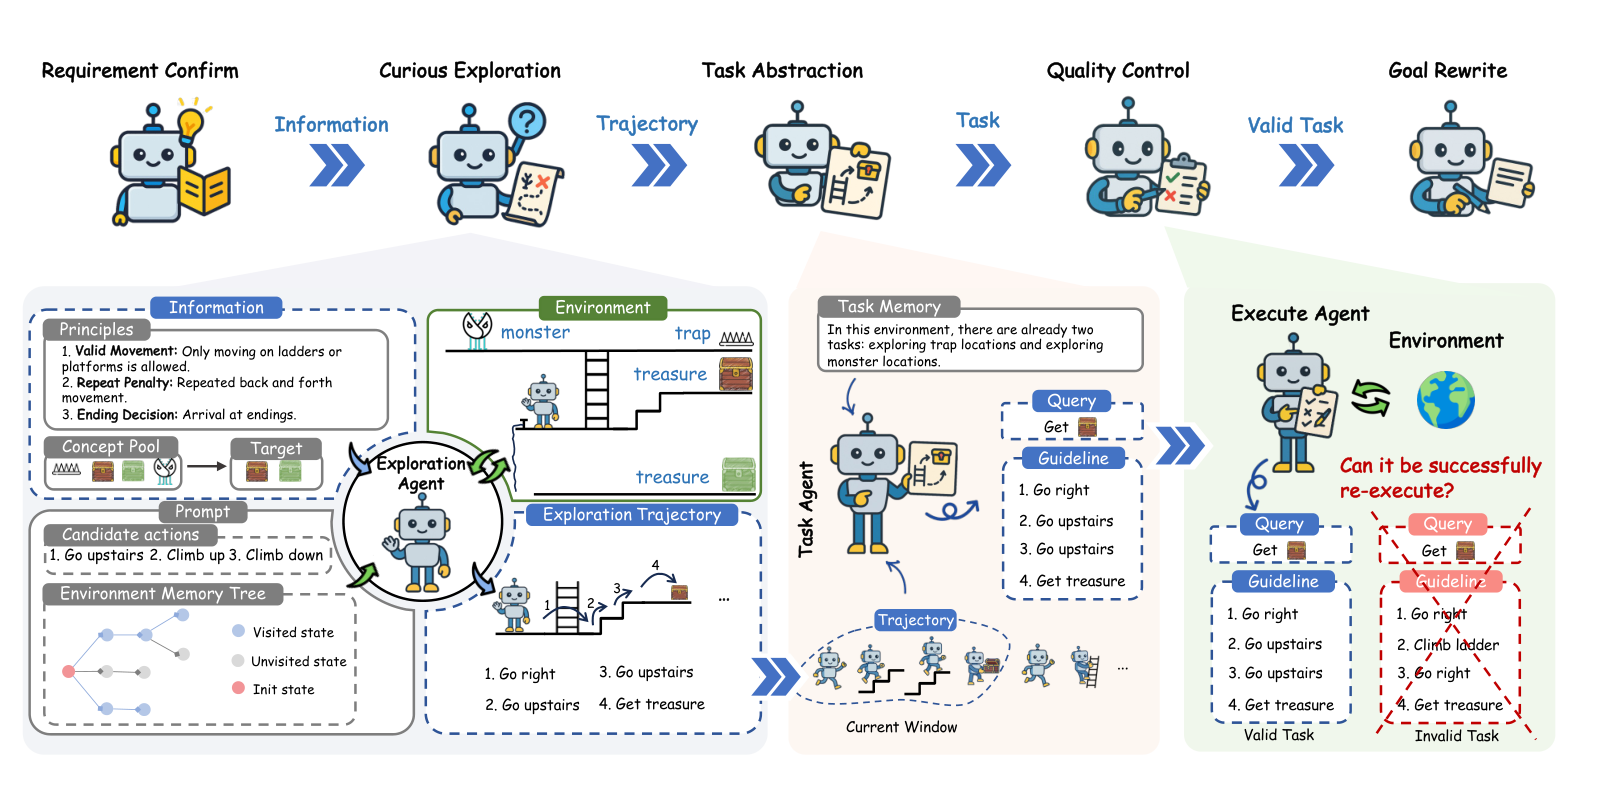
Curiosity-guided exploration grounds synthetic tasks in executable environments for agentic reinforcement learning.以好奇心引导环境探索,在可执行的环境中合成智能体强化学习任务。
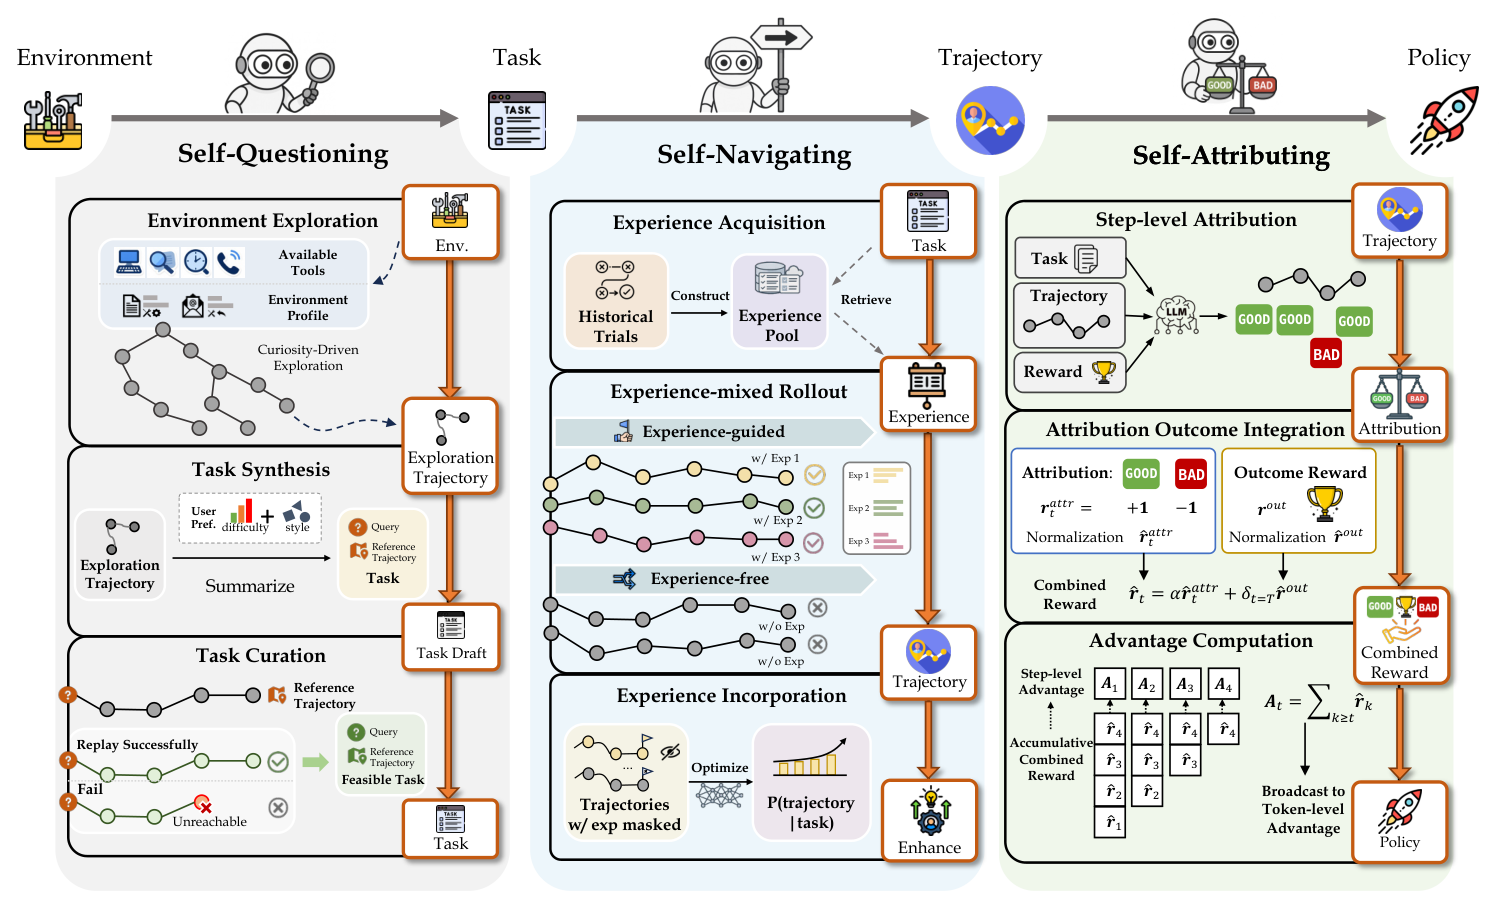
Combines self-questioning, self-navigating, and self-attributing to help agents learn from their own experience.结合自主提问、自主探索与自主归因,让智能体从自身经验中持续学习。
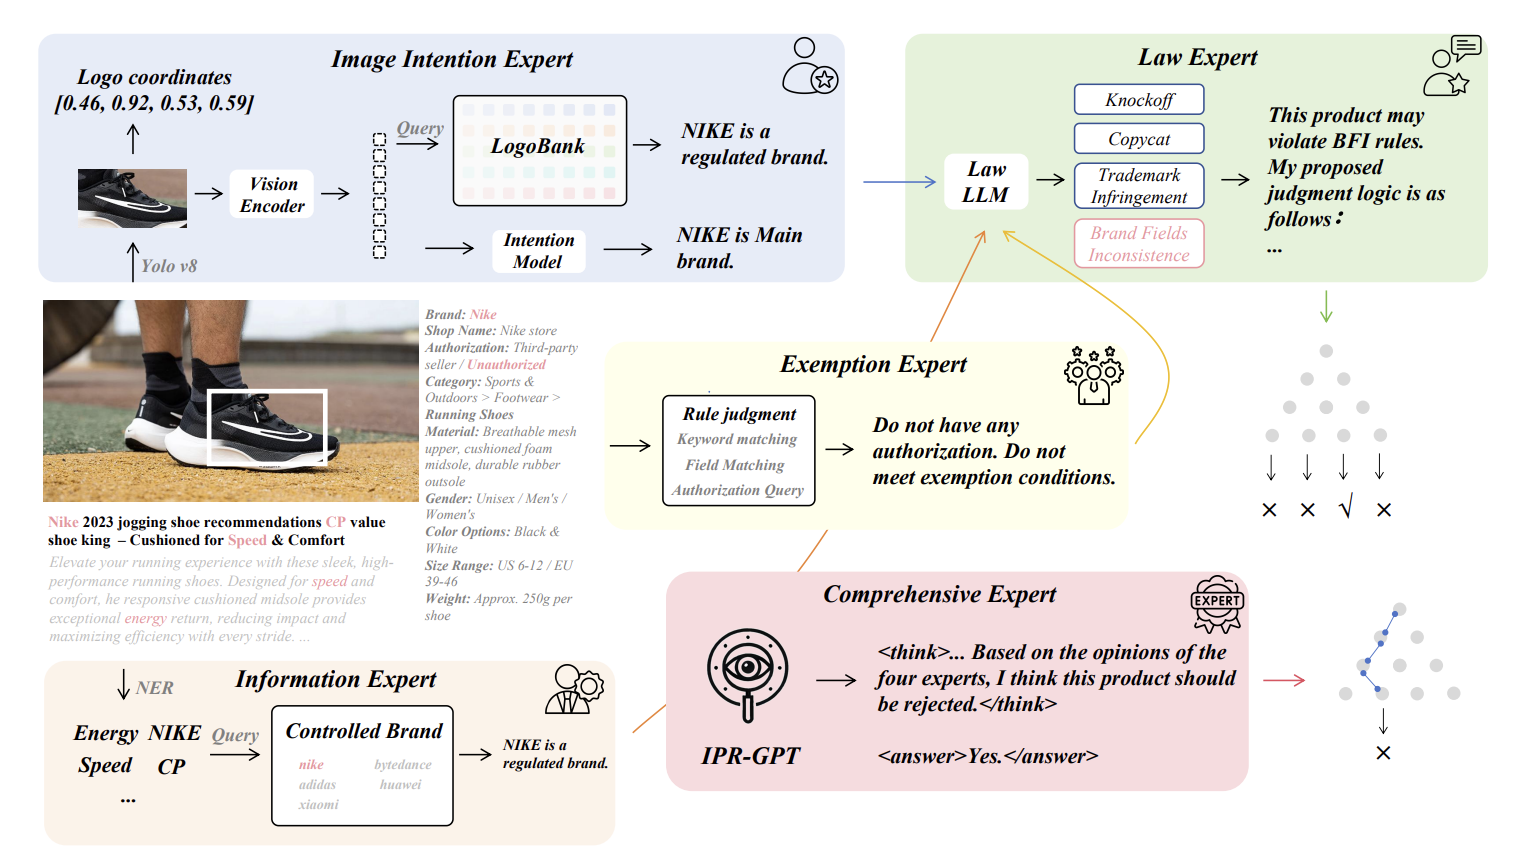
A multi-agent audit framework combines specialized small models for automated intellectual-property audits.将多个专门化小模型组合为多智能体审核框架,用于知识产权自动审核。
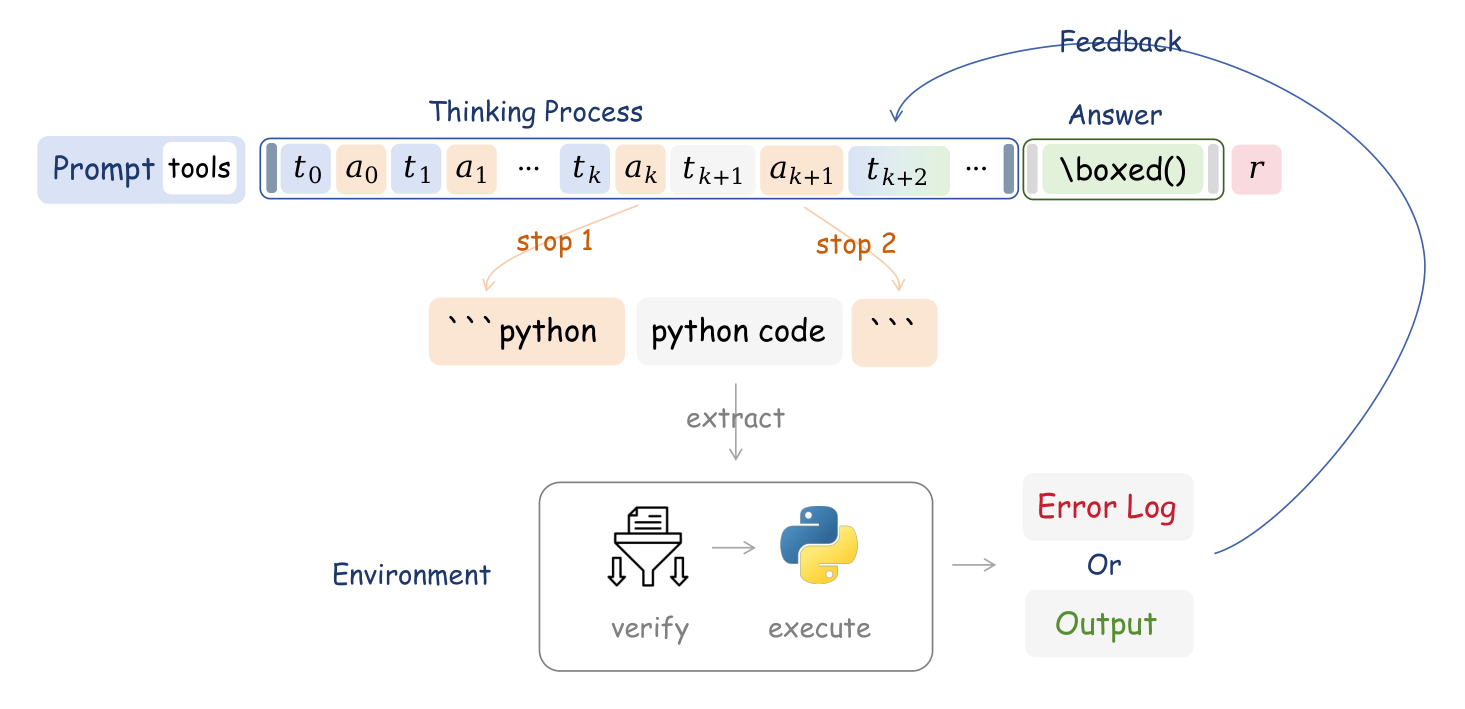
Studies how reinforcement learning teaches models to use code for mathematical reasoning, and how this ability scales.研究强化学习如何让模型自主调用代码进行数学推理,以及这种能力的规模化规律。
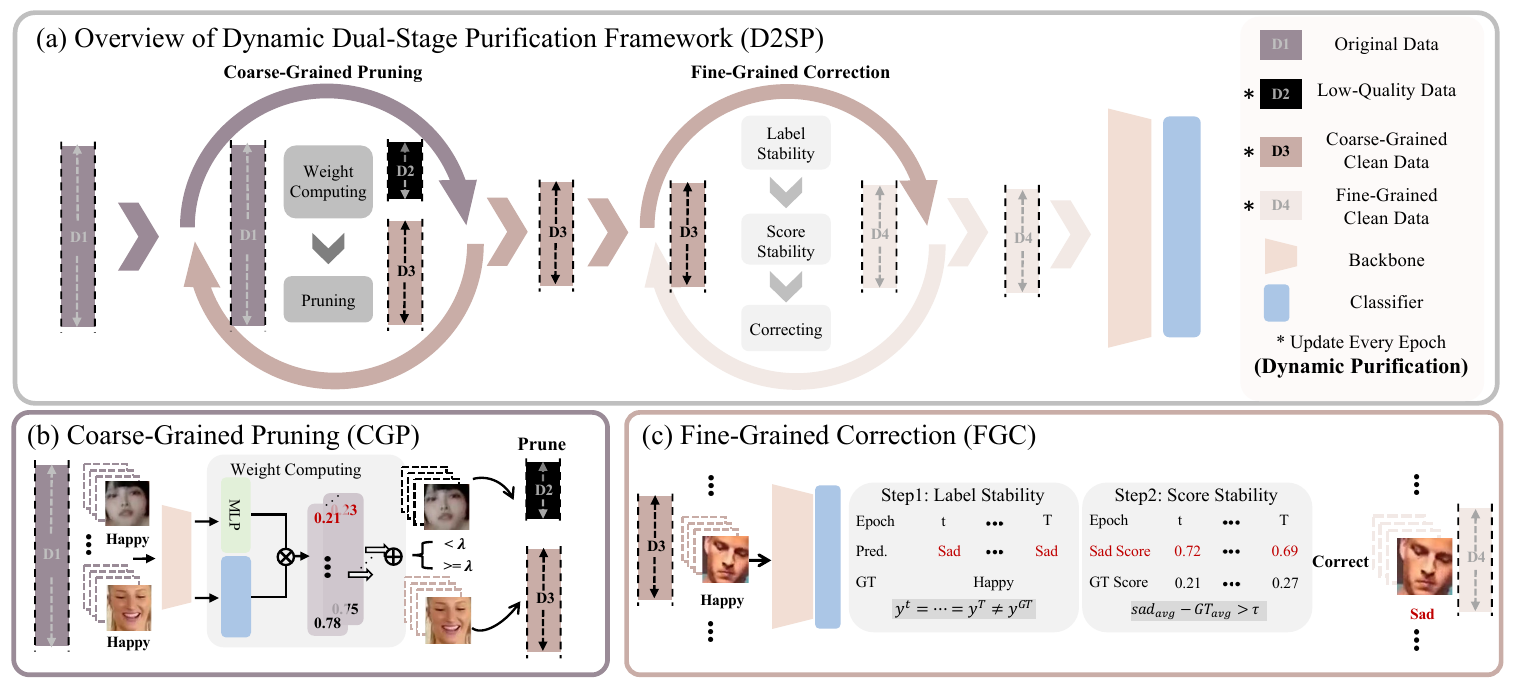
D2SP combines coarse sample pruning with fine label correction to mitigate low-quality inputs and annotation noise in dynamic facial expression recognition.D2SP 结合粗粒度样本剪枝与细粒度标签修正,缓解动态表情识别中的低质量输入和标注噪声。
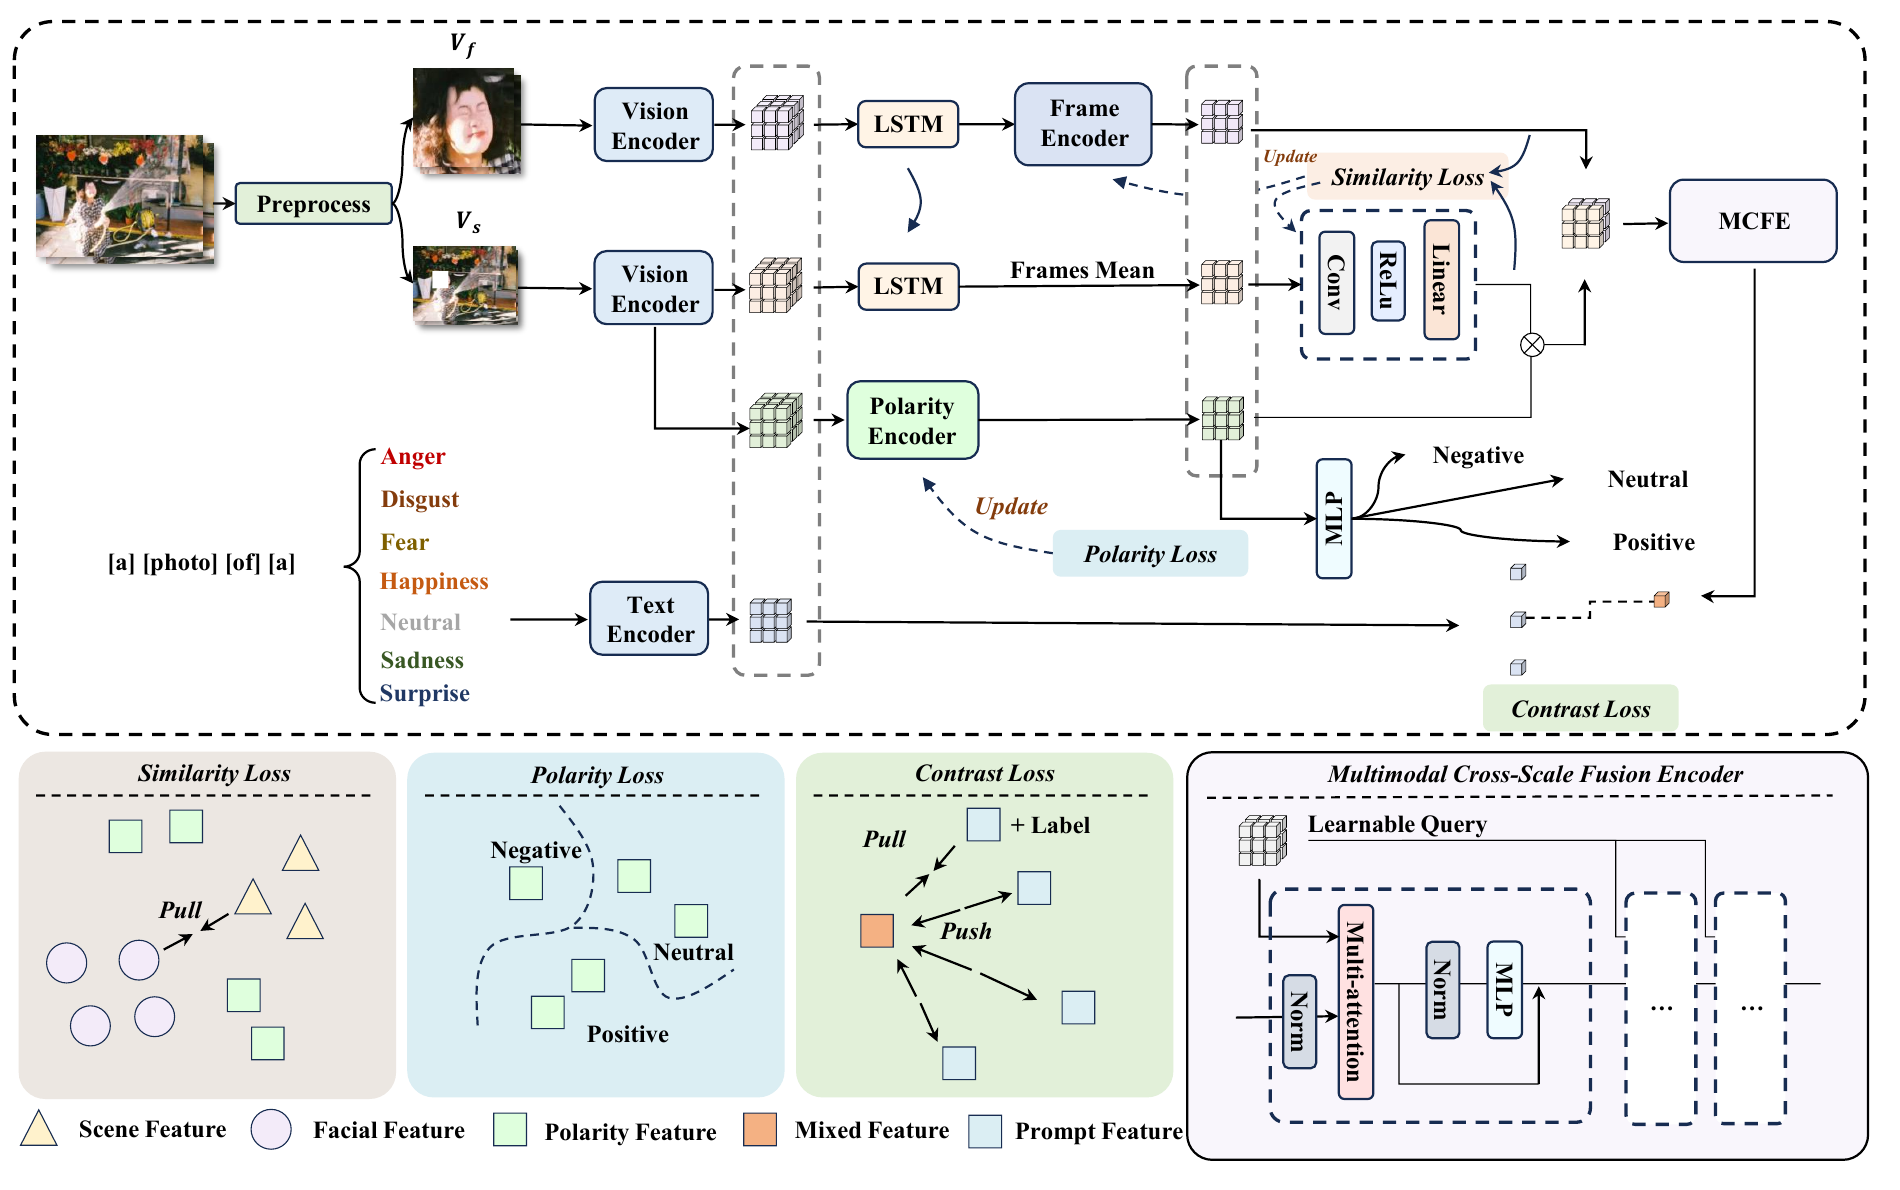
Connects scene context with facial features to support more context-aware emotion recognition.联结场景上下文与面部特征,让情绪识别更充分地理解情境。
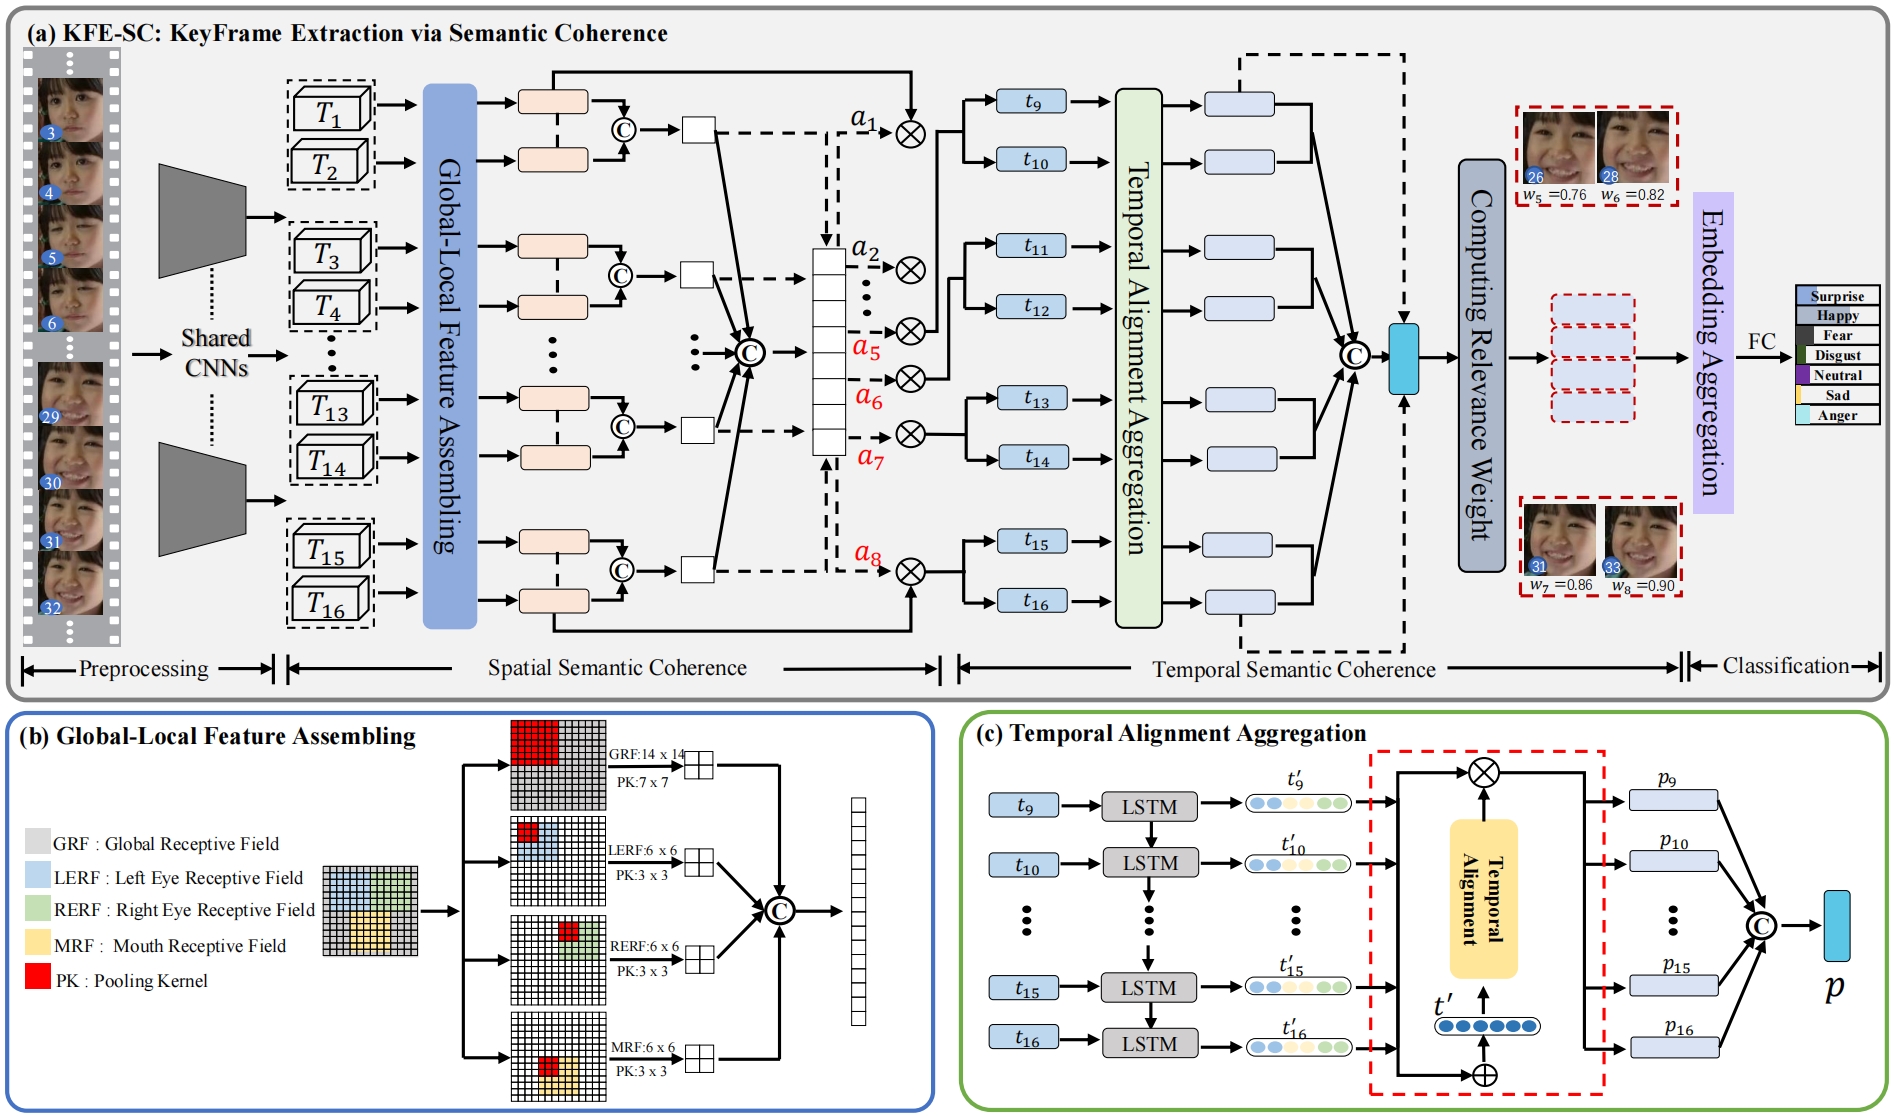
KFE-SC selects expressive video frames from coarse to fine by combining spatial semantic coherence with aligned short- and long-term temporal features.KFE-SC 结合空间语义一致性与长短期时序特征对齐,以由粗到细的方式筛选表情关键帧。
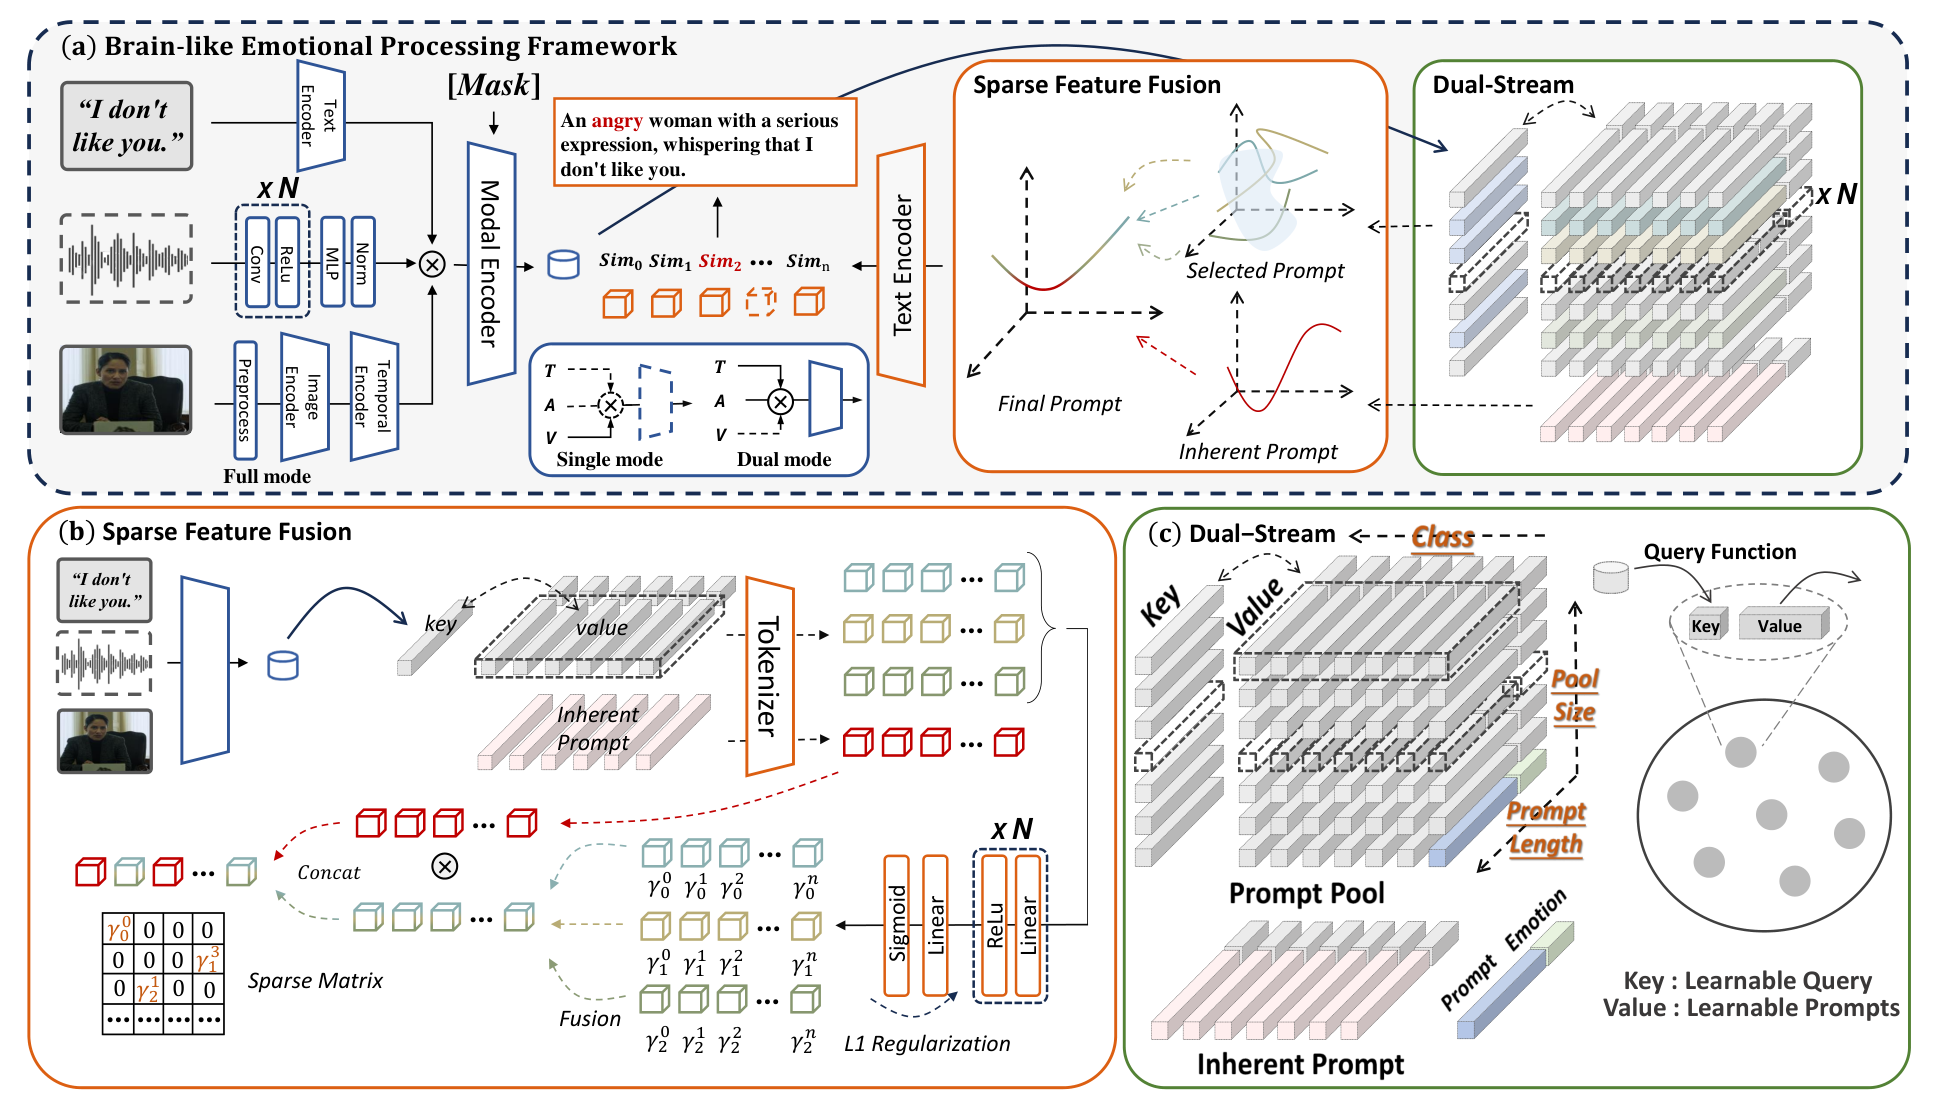
Unifies multimodal emotion signals through a brain-inspired emotional central mechanism.通过脑启发的情感中枢机制,统一建模多模态情绪信号。
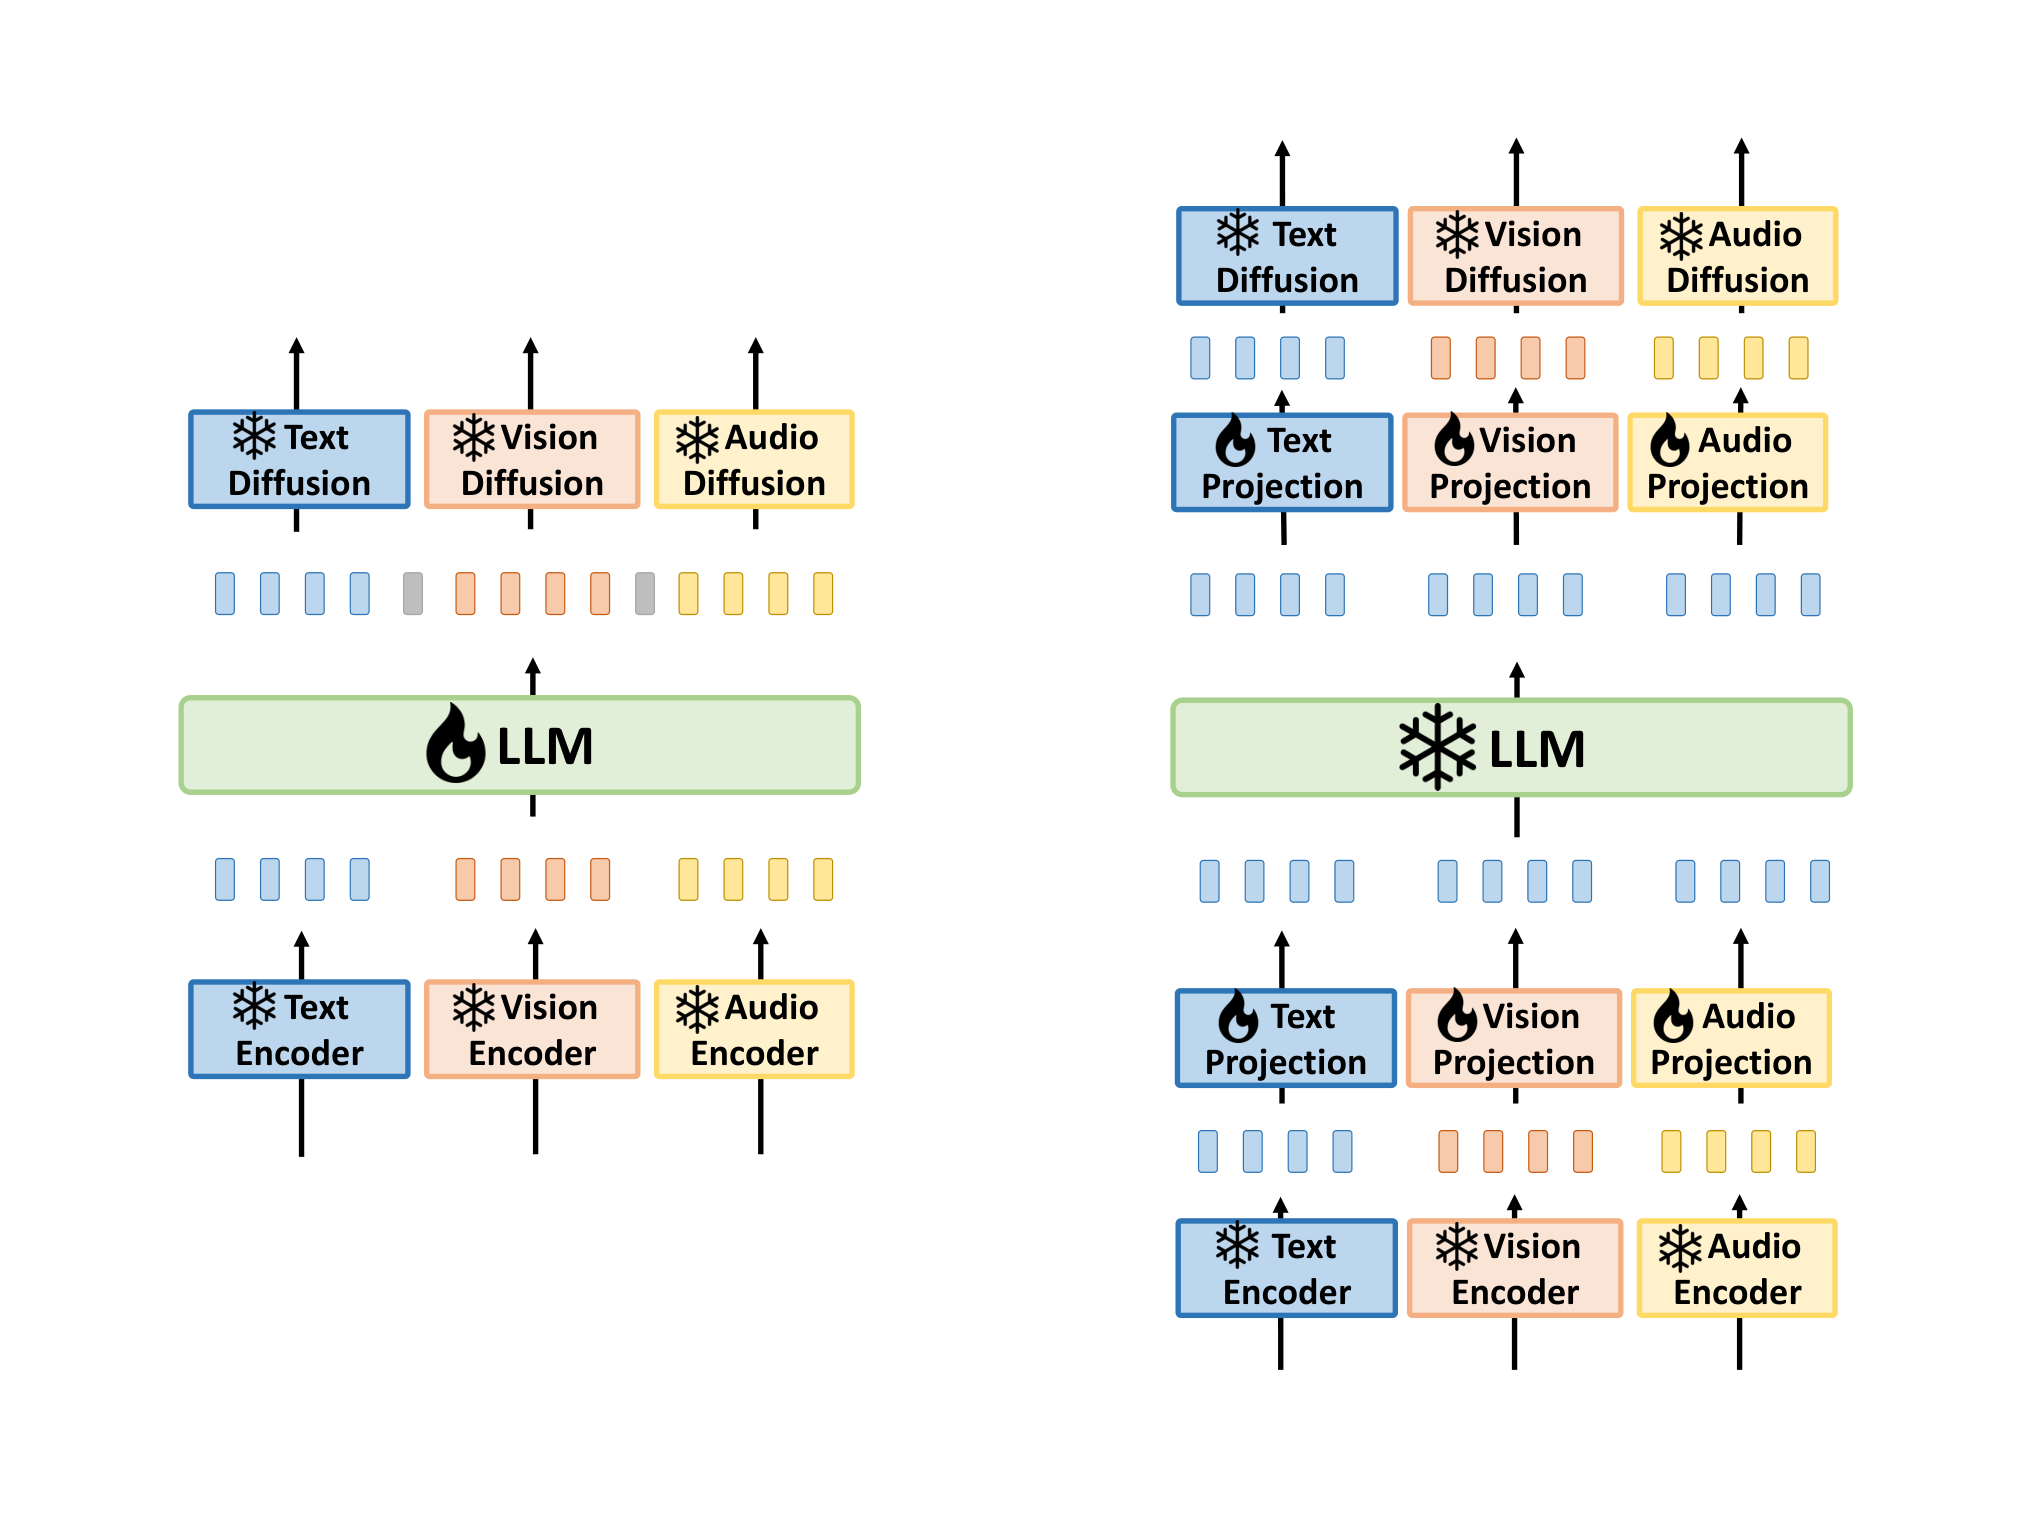
Surveys efficient multimodal models, their training strategies, and the path toward world models.梳理高效多模态模型、训练策略及其向世界模型演进的路径。
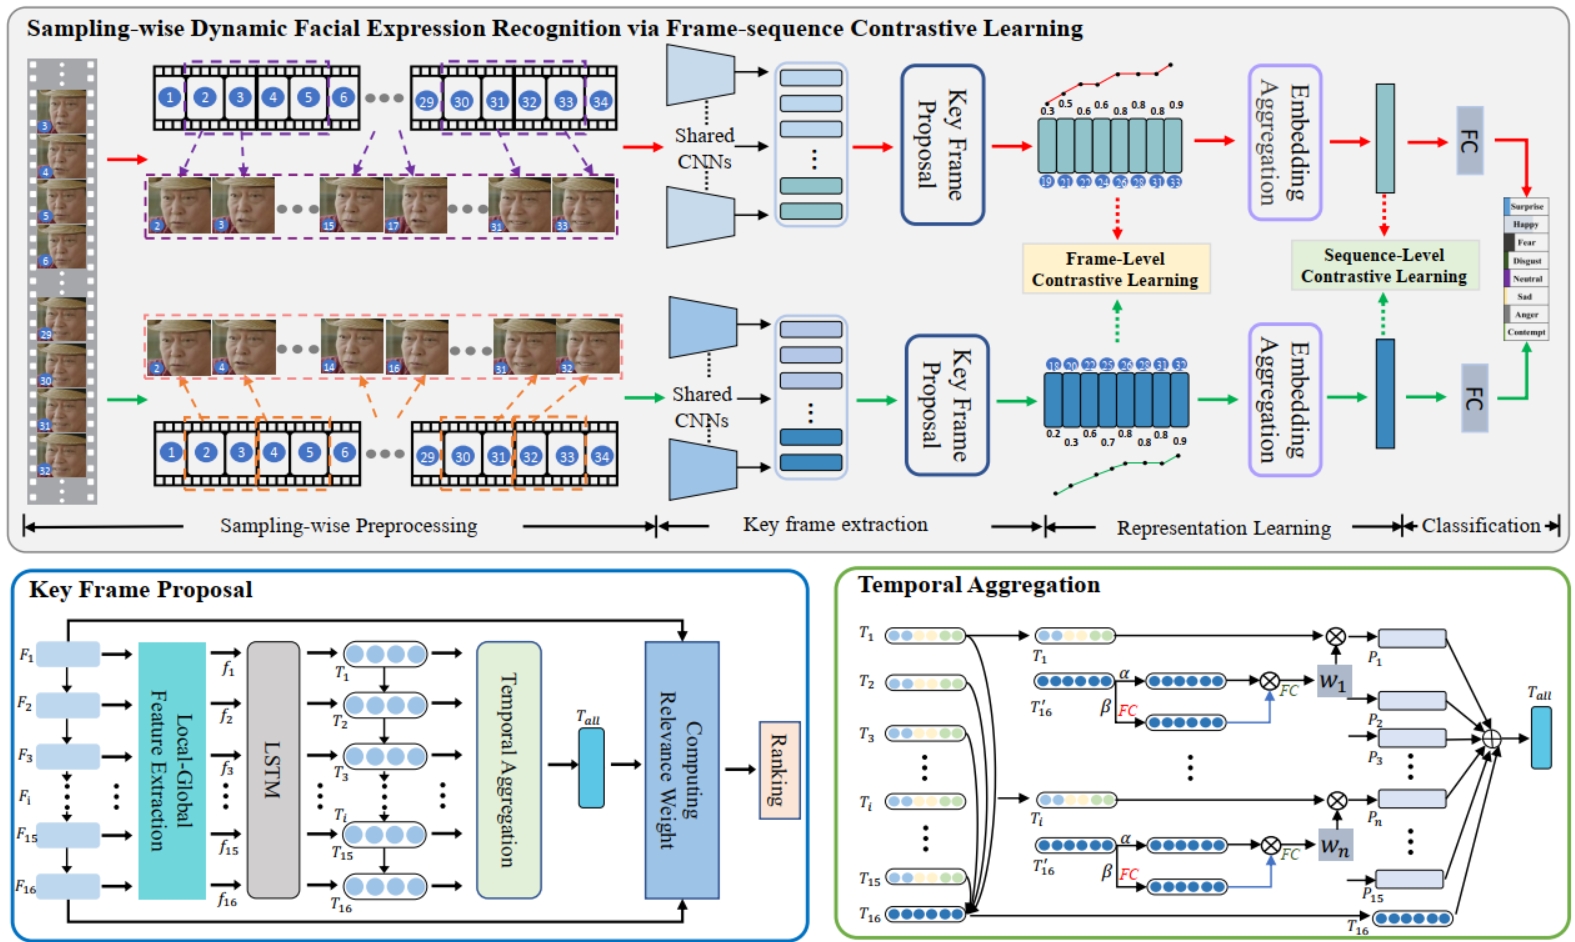
SW-FSCL combines dual-stream dynamic sampling, key-frame weighting and frame-sequence contrastive learning to reduce neutral and noisy frames in expression recognition.SW-FSCL 结合双流动态采样、关键帧加权和帧序列对比学习,减轻中性帧与噪声帧对表情识别的影响。
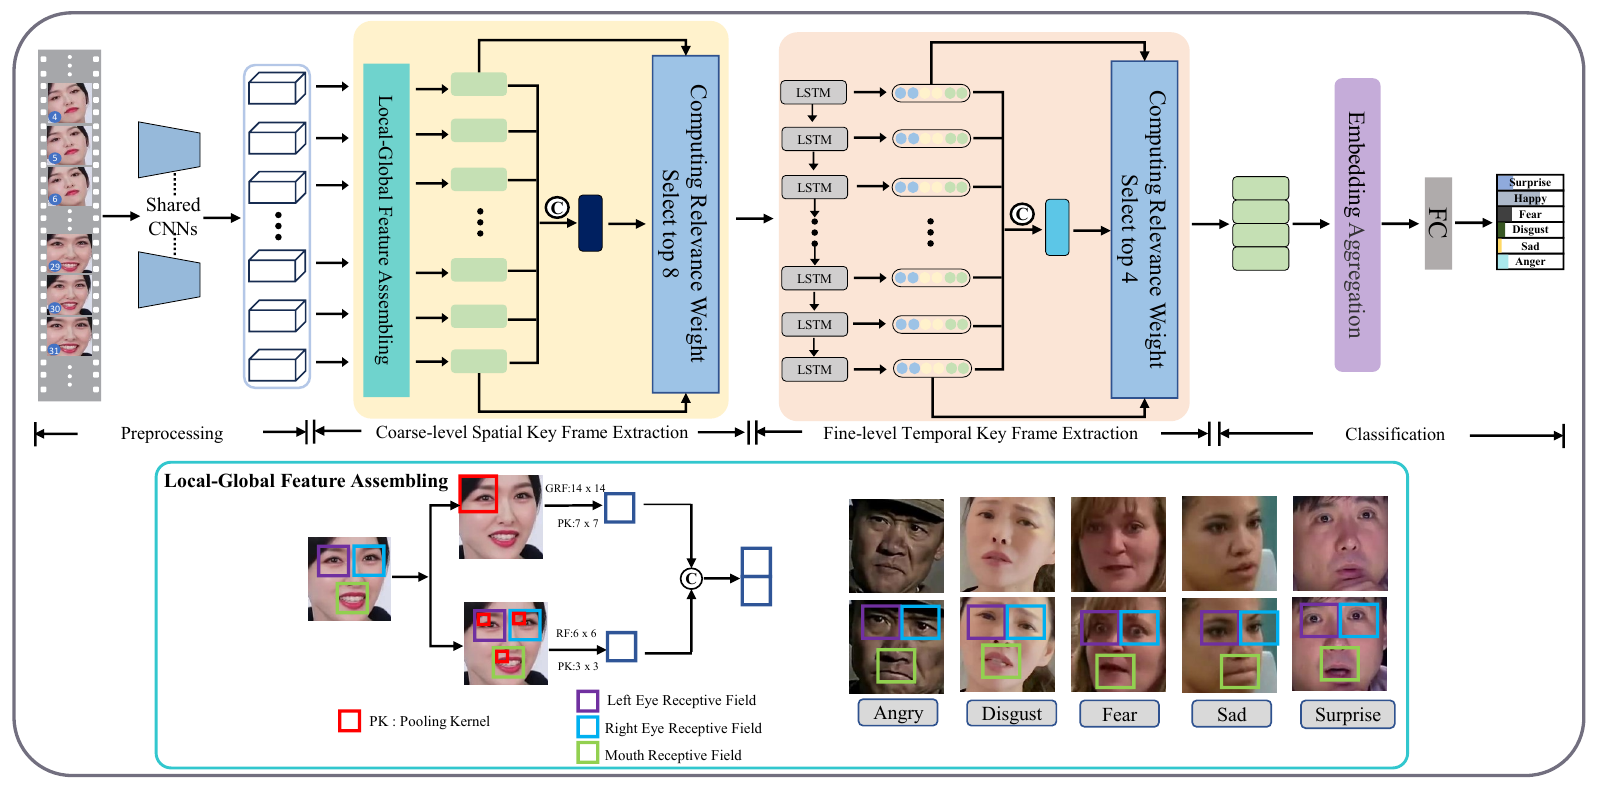
C2F-KFS selects expression peaks through coarse spatial and fine temporal feature extraction to improve dynamic facial expression recognition.C2F-KFS 通过粗粒度空间特征与细粒度时间特征提取筛选表情峰值帧,改进动态表情识别。