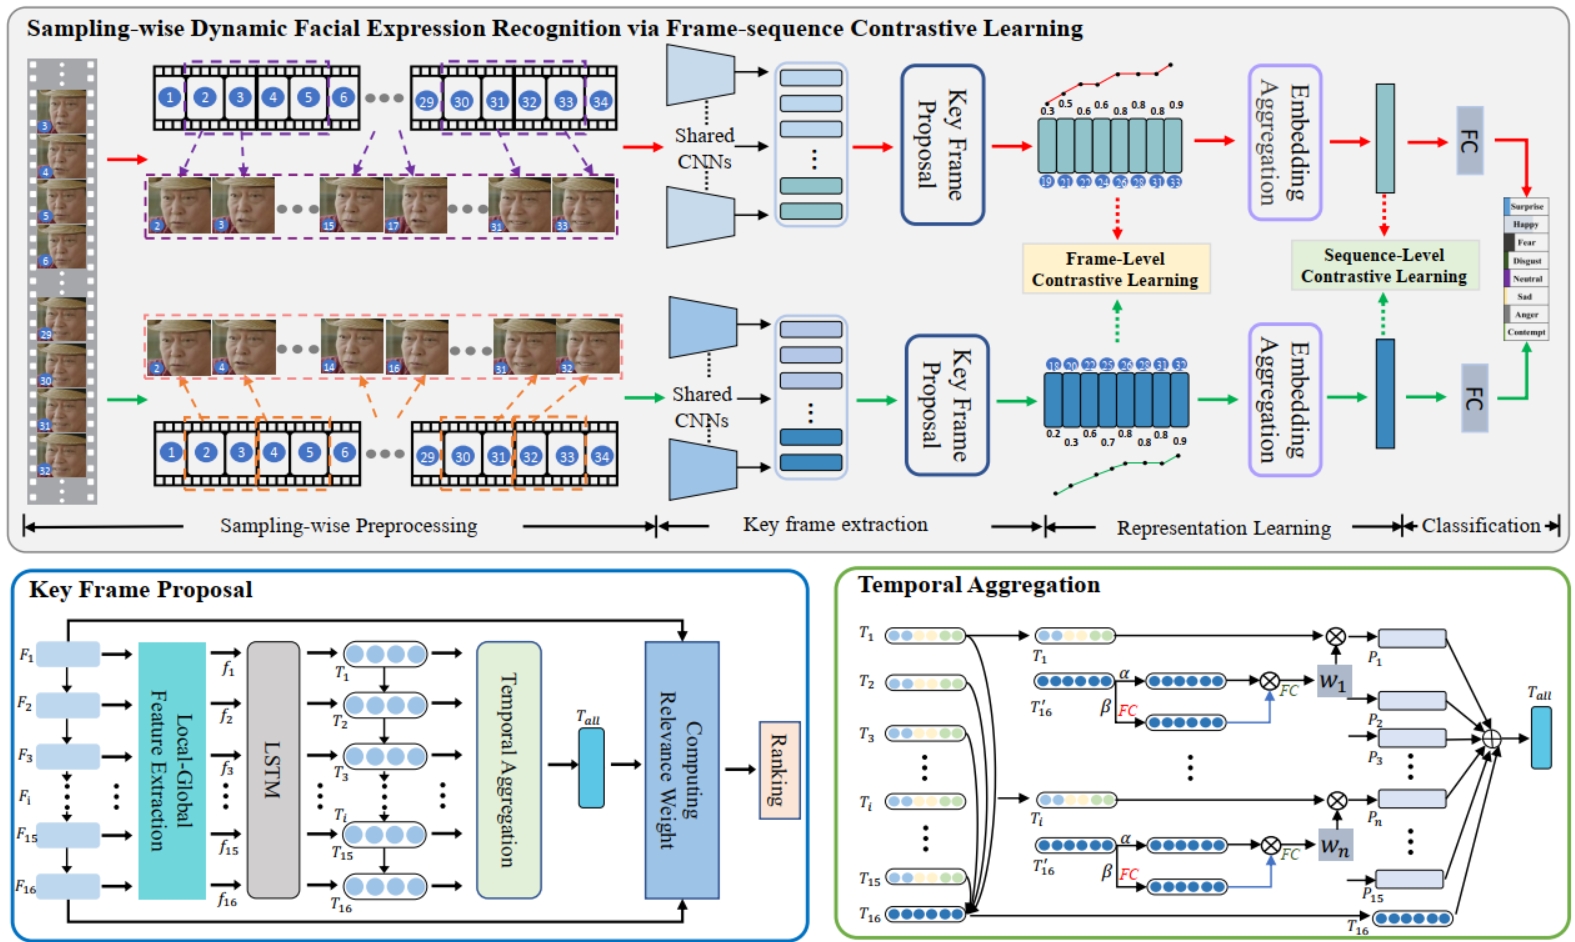
SW-FSCL combines dual-stream dynamic sampling, key-frame weighting and frame-sequence contrastive learning to reduce neutral and noisy frames in expression recognition.
SW-FSCL 结合双流动态采样、关键帧加权和帧序列对比学习,减轻中性帧与噪声帧对表情识别的影响。
Shaoqi Yan, Yan Wang, Xinji Mai, Qing Zhao, Wei Song, Jun Huang, Zeng Tao, Haoran Wang, Shuyong Gao, Wenqiang Zhang. "Empower smart cities with sampling-wise dynamic facial expression recognition via frame-sequence contrastive learning." Computer Communications 2024. https://doi.org/10.1016/j.comcom.2023.12.032