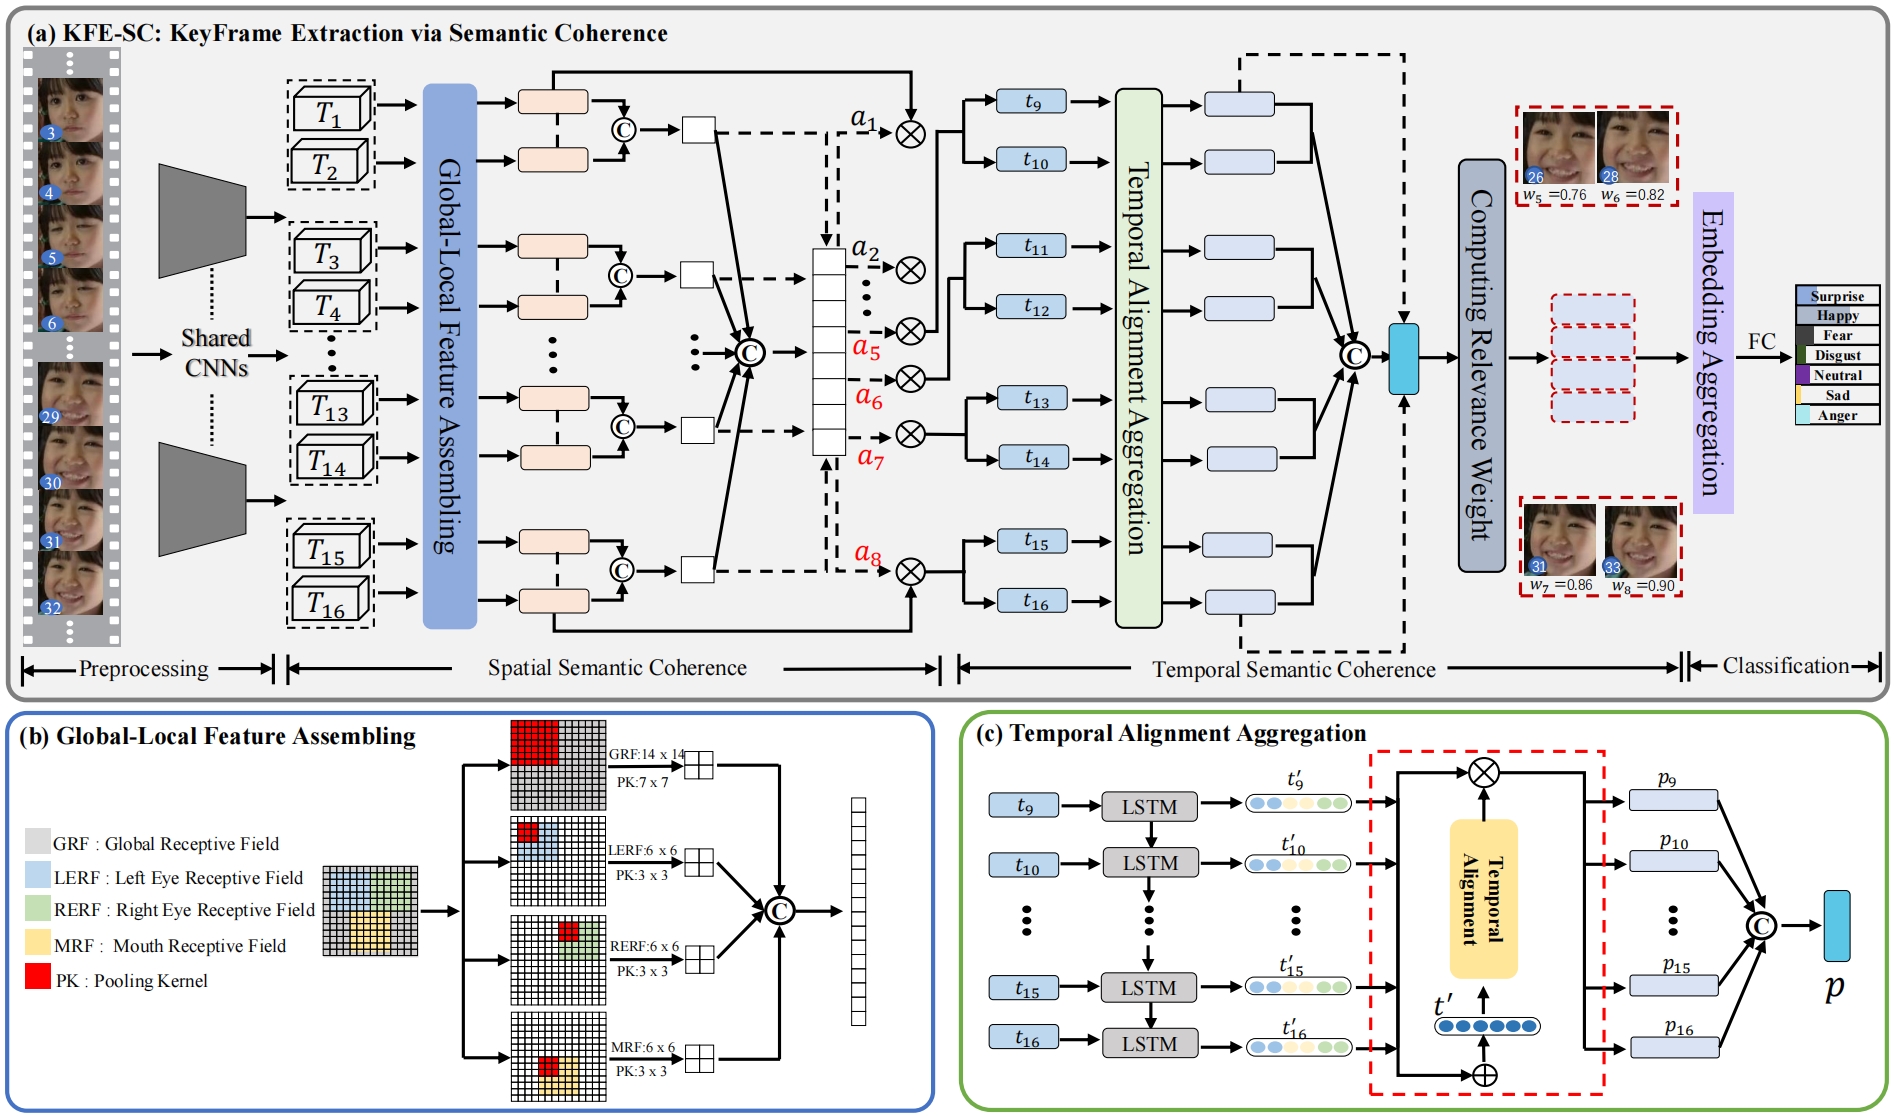
KFE-SC selects expressive video frames from coarse to fine by combining spatial semantic coherence with aligned short- and long-term temporal features.
KFE-SC 结合空间语义一致性与长短期时序特征对齐,以由粗到细的方式筛选表情关键帧。
Shaoqi Yan, Yan Wang, Xinji Mai, Zeng Tao, Wei Song, Qing Zhao, Boyang Wang, Haoran Wang, Shuyong Gao, Wenqiang Zhang. "Observe finer to select better: Learning key frame extraction via semantic coherence for dynamic facial expression recognition in the wild." Information Sciences 2025. https://doi.org/10.1016/j.ins.2024.121415